Template Method Design Pattern

What is a Template Method Design Pattern

The Template Method design pattern is a behavioral design pattern that defines the outline or skeleton of an algorithm in a method but allows some steps of the algorithm to be implemented by subclasses. It promotes code reuse by providing a common structure for related algorithms while allowing specific steps to be customized in the subclasses.

It defines the skeleton of an algorithm in a base class, allowing subclasses to provide specific implementations for certain steps. It enables subclasses to customize specific parts of the algorithm while preserving the overall structure.

The Template Method pattern can be used in situations when there is an algorithm, some steps of which could be implemented in multiple different ways. In such scenarios, the Template Method pattern suggests keeping the outline of the algorithm in a separate method referred to as a template method inside a class, which may be referred to as a template class, leaving out the specific implementations of the variant portions (steps that can be implemented in multiple different ways) of the algorithm to different subclasses of this class.

Template Method lets subclasses to override/redefine certain steps of an algorithm without changing the algorithm’s structure.

The template method pattern provides a basic outline, but it allows you to customize and add your own variations to the solution.

Explanation

The Template Method design pattern is a way to create a standardized procedure for solving a problem.

It provides a set of steps that must be followed in a specific order to solve the problem. It lets subclasses to redefine certain steps of an algorithm without changing the algorithm’s structure.

The Template Method pattern is useful when you have a common algorithm with several variations, and you want to avoid code duplication among these variations. Instead of duplicating the common code in each subclass, you define the common algorithm in a base class (or abstract class) as a template method. The template method contains fixed steps of the algorithm that should not be modified and calls abstract or hook methods that the subclasses can override to provide their own implementation.

Key components of the Template Method pattern:

  1. Abstract Class (or Base Class): The abstract class defines the skeleton of the algorithm by providing a template method that orchestrates the steps of the algorithm. It may also include default implementations for some steps. It contains fixed steps of the algorithm and may include abstract methods or hook methods that can be overridden by subclasses.
  2. Concrete Classes (Subclasses): These classes inherit from the abstract class and provide concrete implementations for the abstract or hook methods. Each subclass can customize specific steps of the algorithm without changing the overall structure.
  3. Template Method: The template method is the main method in the abstract class that defines the structure of the algorithm. It calls the individual steps, including both the common steps and the ones to be overridden by subclasses.
  4. Hook Methods: Hook methods are optional methods in the abstract class that subclasses can choose to override if they need additional customization points within the algorithm.

Implementation details

The Template Method design pattern in Java can be implemented by defining a base class with a template method that implements the algorithm, and providing hooks or abstract methods for the subclasses to override. The subclasses then provide their own implementation for the hooks, if necessary to customize the behavior.

** The Template class does not necessarily have to leave the implementation to subclasses in its entirety. Instead, as part of providing the outline of the algorithm, the Template class can also provide some amount of implementation that can be considered as invariant across different implementations. It can even provide default implementation for the variant parts, if appropriate. Only specific details will be implemented inside different subclasses. This type of implementation eliminates the need for duplicate code, which means a minimum amount of code to be written.

  • Template method should consist of certain steps whose order is fixed and for some of
    the methods; implementation differs from base class to subclass. Template method should be final.
// Abstract Class (Template)
abstract class Beverage {


    // template method - that specifies the steps that define the algorithm
    public final void prepareBeverage() {
        boilWater();
        brew();
        pourInCup();
        addCondiments();
    }

    // some of the steps common
    protected void boilWater() {
        System.out.println("Boiling water");
    }

    // some of the steps, the subclasses can provide specific implementation
    protected abstract void brew();

    protected void pourInCup() {
        System.out.println("Pouring into cup");
    }

    protected abstract void addCondiments();
}

// Concrete Class 1
class Coffee extends Beverage {
    @Override
    protected void brew() {
        System.out.println("Brewing coffee");
    }

    @Override
    protected void addCondiments() {
        System.out.println("Adding milk and sugar");
    }
}

// Concrete Class 2
class Tea extends Beverage {
    @Override
    protected void brew() {
        System.out.println("Steeping tea bag");
    }

    @Override
    protected void addCondiments() {
        System.out.println("Adding lemon");
    }
}

// Usage
public class Main {
    public static void main(String[] args) {
        Beverage coffee = new Coffee();
        Beverage tea = new Tea();

        System.out.println("Preparing Coffee:");
        coffee.prepareBeverage();

        System.out.println("\nPreparing Tea:");
        tea.prepareBeverage();
    }
}

Output :

Preparing Coffee:
Boiling water
Brewing coffee
Pouring into cup
Adding milk and sugar

Preparing Tea:
Boiling water
Steeping tea bag
Pouring into cup
Adding lemon

In this example, the Beverage class is the abstract class that defines the template method prepareBeverage(), which outlines the beverage preparation process. It includes fixed steps (boilWater() and pourInCup()) and abstract methods (brew() and addCondiments()). The Coffee and Tea classes are concrete subclasses that extend Beverage and provide their specific implementations for brew() and addCondiments().

The Template Method pattern allows the common steps of the beverage preparation process to be shared among the different beverage types while allowing each type to define its unique way of brewing and adding condiments. This leads to better code organization, reusability, and maintainability.

The Template Method pattern is useful in situations where you want to provide a default implementation for a certain algorithm, while allowing subclasses to provide their own specific implementation details for certain steps.


Use cases

  • To implement the invariant parts of an algorithm once and leave it up to subclasses to
    implement the behavior that can vary.
  • When common behavior among subclasses should be factored and localized in a
    common class to avoid code duplication. You first identify the differences in the existing
    code and then separate the differences into new operations. Finally, you replace the
    differing code with a template method that calls one of these new operations.

Template Method Design Pattern – Simple implementation

Abstract Base class – Game

package com.rndayala.designpatterns.templatemethod;

public abstract class Game {
        // this is common method to initalize the video game
	public void initialize() {
		System.out.println("Welcome to EA Sports. Game Initialized..");
	}
	abstract void startPlay();
	abstract void endPlay();
	
	// template method - we mark it as final
	public final void play() {
		initialize();
		startPlay();
		endPlay();
	}

}

Concrete Class – Cricket

package com.rndayala.designpatterns.templatemethod;

public class Cricket extends Game {
	
	@Override
	void startPlay() {
		System.out.println("Cricket Game started. Enjoy the Game!");
	}

	@Override
	void endPlay() {
		System.out.println("Cricket Game Finished.");
	}
}

Concrete Class – Football

package com.rndayala.designpatterns.templatemethod;

public class Football extends Game {
	
	@Override
	void startPlay() {
		System.out.println("Football Game started. Enjoy the Game!");
	}

	@Override
	void endPlay() {
		System.out.println("Football Game Finished.");
	}
}

Client code / Demo

package com.rndayala.designpatterns.templatemethod;

public class Demo {
	public static void main(String[] args) {
		Game game = new Cricket();
		game.play();
		
		System.out.println();
		
		game = new Football();
		game.play();
	}
}

Output :

Welcome to EA Sports. Game Initialized..
Cricket Game started. Enjoy the Game!
Cricket Game Finished.

Welcome to EA Sports. Game Initialized..
Football Game started. Enjoy the Game!
Football Game Finished.

The Template Method design pattern is used in situations where you want to define the skeleton of an algorithm, but allow subclasses to provide the implementation for some of the steps.

When to use the template method design pattern is when you are implementing a common task that has multiple steps, and some of the steps may change based on specific requirements. By using template method pattern, you can define the basic steps and let subclasses implement the specific details for each step. This way, you can maintain the common interface, but still provide the flexibility to change the algorithm as needed.


In Java, the Template Method pattern is widely used to define the structure of algorithms while allowing subclasses to provide specific implementations for certain steps.

Observer Design Pattern

What is an Observer Design Pattern

The Observer design pattern is a behavioral software design pattern that is used to establish a one-to-many dependency between objects. In this pattern, when one object (known as the subject) changes its state, all its dependents (known as observers) are automatically notified and updated accordingly.

It allows multiple objects to be notified of changes in the state of another object without requiring them to know the specifics of the subject.

The Observer Design Pattern is a way for one object, known as the subject, to send updates to multiple other objects, known as observers, when it changes.

An example of this pattern in real life could be a weather service sending updates to different weather apps when the weather changes. The weather service is the subject and the weather apps are the observers.


Explanation

The Observer Design Pattern is a way for one object, known as the subject, to notify multiple other objects, known as observers, about changes in its state. The subject maintains a list of its observers and notifies them when its state changes.

In observer design pattern multiple observer objects registers with a subject for change notification. When the state of subject changes, it notifies the observers.

Objects that listen or watch for change are called observers and the object that is being watched for is called subject.

Pattern involved is also called as publish-subscribe pattern.

  • Subject provides interface for observers to register and unregister themselves with the
    subject.
  • Subject knows who its subscribers are.
  • Multiple observers can subscribe for notifications.
  • Subject publishes the notifications.
  • Subject just sends the notification saying the state has changed. It does not pass any state information.
  • Once the notification is received from subject, observers call the subject and get data
    that is changed.

In some implementations, along with the notification, state is also passed so that the observer need not query back to know the status. It is better not to do this way.

There are 4 participants in the Observer pattern:

  • Subject, which is used to register observers. Objects use this interface to register as
    observers and also to remove themselves from being observers.
  • Observer defines an updating interface for objects that should be notified of changes in a subject. All observers need to implement the Observer interface. This interface has a method update (), which gets called when the Subject’s state changes.
  • ConcreteSubject, stores the state of interest to ConcreteObserver objects. It sends a
    notification to its observers when its state changes. A concrete subject always implements the Subject interface. The notifyObservers () method is used to update all the current observers whenever the state changes.
  • ConcreateObserver maintains a reference to a ConcreteSubject object and implements the Observer interface. Each observer registers with a concrete subject to receive updates.

This pattern can be useful in situations where multiple objects need to stay updated with the state of a single object, and the objects do not need to interact directly with each other.

This pattern is widely used in many different applications, such as GUI applications, event-driven systems, and reactive programming. It is a fundamental pattern that can help you to design more flexible and scalable systems.

Benefits

The Observer design pattern offers several benefits, making it a valuable tool in software development. Here are some of the key benefits of using the Observer pattern:

  1. Loose coupling: The Observer pattern promotes loose coupling between the subject and its observers. Observers don’t need to know the specifics of the subject’s implementation; they only rely on the common Observer interface. This reduces the dependencies between classes, making the code more maintainable and flexible.
  2. Extensibility: Introducing new observers becomes easy. You can create new observer classes without modifying the subject. This makes it simple to add new functionalities to a system without affecting existing code.
  3. Reusability: Observers can be reused in different contexts with different subjects. This reusability is possible because of the separation of concerns provided by the Observer pattern.
  4. Event handling: The Observer pattern is commonly used in event-driven systems. When an event occurs, the subject notifies its observers, and they can respond to the event accordingly. This facilitates a clean and efficient way of handling events in the application.
  5. Decoupled UI components: In graphical user interfaces (GUIs), the Observer pattern is often used to ensure that the UI components are decoupled from the underlying data. UI components can register themselves as observers to receive updates when the data changes, allowing for a responsive and synchronized user interface.
  6. Real-time updates: The Observer pattern is useful in scenarios where real-time updates are needed. For example, in chat applications or stock market monitoring systems, observers can be notified immediately when new messages or stock prices arrive.
  7. Maintainability: By separating the concerns of the subject and its observers, the codebase becomes easier to maintain. Changes to one part of the system are less likely to affect other parts, reducing the risk of introducing bugs and making it easier to refactor or add new features.
  8. Scalability: The Observer pattern enables a scalable architecture by allowing multiple observers to be added or removed dynamically at runtime. This is particularly valuable in large applications where different components need to react to changes in a subject independently.

Overall, the Observer design pattern provides a powerful mechanism for building flexible and decoupled systems, enabling better code organization and easier maintenance. It is widely used in various domains, including user interfaces, event handling, and real-time applications.

Implementation

Let us take a blog and subscriber example for observer design pattern sample implementation. Assume that there is a blog and users register to that blog for update.
When a new article is posted in the blog, it will send update to the registered users saying a new article is posted. Then the user will access the blog and read the new article posted. In this example, blog is the subject and user is the observer.

Subject interface

package com.rndayala.designpatterns.observable;

// Subject interface
public interface Subject {
	void registerObserver(Observer observer);
	void unregisterObserver(Observer observer);
	void notifyObservers();
	Object getUpdate();
}

Observer interface

package com.rndayala.designpatterns.observable;

// Observer interface
public interface Observer {
	void update(Subject subject);

}

Concrete Subject implementation – Blog class

package com.rndayala.designpatterns.observable;

import java.util.ArrayList;
import java.util.List;

// Concrete Subject class 
public class Blog implements Subject {
	// Concrete Subject maintains list of observers
	private List<Observer> observers = null;
	// this instance variable maintains the state of Concrete subject
	private String blogContent;
	
	public Blog() {
		System.out.println("Initializing subject(blog)..");
		this.observers = new ArrayList<Observer>();
		blogContent = "";
	}
	
	@Override
	public void registerObserver(Observer observer) {
		System.out.println("registering an observer!");
		observers.add(observer);		
	}
	
	@Override
	public void unregisterObserver(Observer observer) {
		System.out.println("un-registering an observer!");
		observers.remove(observer);
	}

        // when the state of subject changes, we need to notify observers
	public void postNewArticle(String data) {
		blogContent = data;
		notifyObservers();
	}
	
	@Override
	public void notifyObservers() {
                // for each observer, call the update() method allowing observer to react to the change in subject state		
		for (Observer observer : observers) {
			observer.update(this);
			System.out.println("Observer notified!!");
		}
	}
	
	@Override
	public Object getUpdate() {
		return blogContent;
	}
	
        // method to return the list of observers registered with the subject
	public List<Observer> getObserversList() {
		return observers;
	}
}

Concrete observer implementation – User class

package com.rndayala.designpatterns.observable;

public class User implements Observer {
	private Object article;


        // on invocation of update() method, the observer will update its own state.
	@Override
	public void update(Subject subject) {
		article = subject.getUpdate();		
	}

	public Object getArticle() {
		return article;
	}

}

Client code – Demo program

package com.rndayala.designpatterns.observable;

import java.util.List;

public class Demo {
	public static void main(String[] args) {
		Blog blog = new Blog();
		User user1 = new User();
		User user2 = new User();
		List<Observer> list = null;
		
		blog.registerObserver(user1);
		blog.registerObserver(user2);
		
                // change the state of subject by posting a new article
		blog.postNewArticle("Observer pattern Explained!");

		list = blog.getObserversList();
		
		for(Observer observer : list) {
			System.out.println("Get content : " + ((User)observer).getArticle());
		}		
		
                // remove an observer		
		blog.unregisterObserver(user2);

		blog.postNewArticle("Singleton pattern Explained!");

		list = blog.getObserversList();
		
		for(Observer observer : list) {
			System.out.println("Get content : " + ((User)observer).getArticle());
		}

	}
}

Output :

Initializing subject(blog)..
registering an observer!
Observer notified!!
Observer notified!!
Get content : Observer pattern Explained!
un-registering an observer!
Observer notified!!
Get content : Singleton pattern Explained!

When the state of the subject changes, it calls the notifyObservers() method which in turn calls the update method on each of its observers, allowing them to react to the change in subject’s state.


Use cases

The Observer design pattern is typically used in situations where there is a one-to-many relationship between objects and when changes in one object need to be reflected in other objects.

Some common use cases of the Observer pattern are:

1. Implementing a model-view-controller architecture where changes in the model are notified to the views.

2. Implementing event-driven systems, such as user interfaces, where changes in one component trigger updates in other components.

3. Implementing a publish-subscribe system where events are published to multiple subscribers.

4. Implementing a logging system, where changes in the log data need to be notified to multiple log listeners.

5. Implementing a stock ticker system, where changes in the stock prices need to be notified to multiple subscribers.

In all these use cases, the Observer pattern allows the objects to be loosely coupled, so that changes in one object don’t affect the other objects directly. Instead, the changes are notified to the objects that need to be updated.


Observer Design Pattern implementation using Weather station scenario

Here’s a Java code example of the Observer design pattern using the weather station scenario:

When the weather station’s temperature changes, it notifies all its attached observers (TemperatureDisplay and Fan). The TemperatureDisplay then prints the updated temperature, while the Fan turns on or off based on the temperature threshold.

import java.util.ArrayList;
import java.util.List;

// Observer interface
interface Observer {
    void update(int temperature);
}

// Subject
class WeatherStation {
    private List<Observer> observers = new ArrayList<>();
    private int temperature;

    public void attachObserver(Observer observer) {
        observers.add(observer);
    }

    public void detachObserver(Observer observer) {
        observers.remove(observer);
    }

    public void setTemperature(int temperature) {
        this.temperature = temperature;
        notifyObservers();
    }

    // here, while notifying observer, we are sending the state also
    private void notifyObservers() {
        for (Observer observer : observers) {
            observer.update(temperature);
        }
    }
}

// Concrete Observer
class TemperatureDisplay implements Observer {
    @Override
    public void update(int temperature) {
        System.out.println("Temperature Display: " + temperature + " degrees Celsius");
    }
}

// Concrete Observer
class Fan implements Observer {
    @Override
    public void update(int temperature) {
        if (temperature > 25) {
            System.out.println("Fan: Turning on the fan.");
        } else {
            System.out.println("Fan: Turning off the fan.");
        }
    }
}

// Usage
public class Main {
    public static void main(String[] args) {
        WeatherStation weatherStation = new WeatherStation();
        TemperatureDisplay tempDisplay = new TemperatureDisplay();
        Fan fan = new Fan();

        weatherStation.attachObserver(tempDisplay);
        weatherStation.attachObserver(fan);

        weatherStation.setTemperature(20);
        weatherStation.setTemperature(30);
    }
}

Output :

Temperature Display: 20 degrees Celsius
Fan: Turning off the fan.
Temperature Display: 30 degrees Celsius
Fan: Turning on the fan.

This example demonstrates how the WeatherStation subject notifies its attached observers (TemperatureDisplay and Fan) about changes in the temperature, and each observer reacts accordingly.

Builder Design Pattern

What is a Builder Design Pattern

Builder is a creational design pattern that lets you construct complex objects step by step. The pattern allows you to produce different types and representations of an object using the same construction code.

It decouples the construction process from the object representation, allowing for the step-by-step creation of objects with different configurations.

The need ?

Imagine a complex object that requires laborious, step-by-step initialization of many fields and nested objects. Such initialization code is usually buried inside a monstrous constructor with lots of parameters. Or even worse: scattered all over the client cod

In general, the details of object construction – the constructors, such as instantiating and initializing the components that make up the object, are kept within the object, often as part of its constructor. This type of design closely ties the object construction process with the components that make up the object. This approach is suitable as long as the object under construction is simple and the object construction process is definite and always produces the same representation of the object.

However, this design may not be effective when the object being created is complex and the series of steps constituting the object creation process can be implemented in different ways, thus producing different representations of the object.

If we try to keep all such instantiation steps within the object, the object can become bulky (construction bloat) and less modular. Subsequently, adding a new implementation or making changes to an existing implementation requires changes to the existing code.

The Idea / Intent

The Builder pattern suggests that you extract the object construction code out of its own class and move it to separate objects called builders.

The Builder pattern suggests moving the construction logic out of the object class to a separate class referred to as a builder class. There can be more than one such builder classes, each with different implementations for the series of steps to construct the object. Each builder implementation results in a different representation of the object.

The intent of the Builder Pattern is to separate the construction of a complex object
from its representation
, so that the same construction process can create different
representations.

This type of separation reduces the object size.

Adding a new implementation (i.e., adding a new builder) becomes easier. The object construction process becomes independent of the components that make up the object. This provides more control over the object construction process.

Explanation

Builder doesn’t require products to have a common interface. That makes it possible to produce different products using the same construction process.

Builder pattern allows you to create different configurations of an object step by step, providing a more flexible and readable way to construct objects with many optional parameters.

The main components of the Builder Design Pattern are:

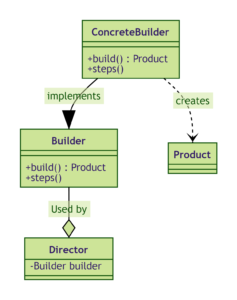
  1. Director (optional) : The Director is responsible for directing the construction of the complex object using the Builder. It controls the order and sequence of the steps required to build the object using the Builder. It is not always necessary to have a Director.
  2. Builder Interface / Abstract class : The Builder is an interface or an abstract class that declares the construction steps and methods for creating a complex object. It typically includes methods for setting various attributes and returning the final product.
  3. Concrete Builder: Concrete Builders are implementations of the Builder interface that provide specific implementation details for constructing different parts of the complex object. Each Concrete Builder is responsible for building a particular variant of the object. It also, Provides an interface for retrieving the product.
  4. Product: The Product is the complex object being constructed. It typically contains multiple attributes and configurations. It is the final object resulting from the Builder’s construction process.

The Builder pattern suggests using a dedicated object referred to as a Director, which is responsible for invoking different builder methods required for the construction of the final object.

–> Once the object is constructed, the client object can directly request from the builder the fully constructed object. To facilitate this process, a new method getObject() can be declared in the common Builder interface to be implemented by different concrete builders.

Ref – https://refactoring.guru/design-patterns/builder

Benefits

The Builder pattern can be applied when construction of various representations of the product involves similar steps that differ only in the details.

The same construction process can create different representations.

Examples

Usage examples: The Builder pattern is a well-known pattern in Java world. It’s especially useful when you need to create an object with lots of possible configuration options.

Builder is widely used in Java core libraries:

Identification: The Builder pattern can be recognized in a class, which has a single creation method and several methods to configure the resulting object. Builder methods often support chaining (for example, someBuilder.setValueA(1).setValueB(2).create()).

Implementation

CarType

package com.rndayala.designpatterns.builder;

// Enum that sepcifies the type of Car
public enum CarType {
    CITY_CAR, SPORTS_CAR, SUV
}

Product feature 1 : Engine

package com.rndayala.designpatterns.builder;

/**
 * Just another feature of a Car product.
 */
public class Engine {
    private final double volume;
    private double mileage;
    private boolean started;

    public Engine(double volume, double mileage) {
        this.volume = volume;
        this.mileage = mileage;
    }

    public void on() {
        started = true;
    }

    public void off() {
        started = false;
    }

    public boolean isStarted() {
        return started;
    }

    public void go(double mileage) {
        if (started) {
            this.mileage += mileage;
        } else {
            System.err.println("Cannot go(), you must start engine first!");
        }
    }

    public double getVolume() {
        return volume;
    }

    public double getMileage() {
        return mileage;
    }
}

Product feature 2 : Transmission

/**
 * Just another feature Car product that specifies the type of Transmission.
 */
public enum Transmission {
    SINGLE_SPEED, MANUAL, AUTOMATIC, SEMI_AUTOMATIC
}

Product feature 3 : TripComputer

package com.rndayala.designpatterns.builder;

/**
 * Just another feature of Car product.
 */
public class TripComputer {

    private Car car;

    public void setCar(Car car) {
        this.car = car;
    }

    public void showFuelLevel() {
        System.out.println("Fuel level: " + car.getFuel());
    }

    public void showStatus() {
        if (this.car.getEngine().isStarted()) {
            System.out.println("Car is started");
        } else {
            System.out.println("Car isn't started");
        }
    }
}

Product feature 4 : GPSNavigator

package com.rndayala.designpatterns.builder;

/**
 * Just another feature of a car.
 */
public class GPSNavigator {
    private String route;

    public GPSNavigator() {
        this.route = "221b, Baker Street, London  to Scotland Yard, 8-10 Broadway, London";
    }

    public GPSNavigator(String manualRoute) {
        this.route = manualRoute;
    }

    public String getRoute() {
        return route;
    }
}

Concrete Product : Car

package com.rndayala.designpatterns.builder;

/**
 * Car is a product class.
 * Product is made up of different components which vary in details for different Product class types.
 */
public class Car {
    private final CarType carType;
    private final int seats;
    private final Engine engine;
    private final Transmission transmission;
    private final TripComputer tripComputer;
    private final GPSNavigator gpsNavigator;
    private double fuel = 0;

    public Car(CarType carType, int seats, Engine engine, Transmission transmission,
               TripComputer tripComputer, GPSNavigator gpsNavigator) {
        this.carType = carType;
        this.seats = seats;
        this.engine = engine;
        this.transmission = transmission;
        this.tripComputer = tripComputer;
        if (this.tripComputer != null) {
            this.tripComputer.setCar(this);
        }
        this.gpsNavigator = gpsNavigator;
    }

    public CarType getCarType() {
        return carType;
    }

    public double getFuel() {
        return fuel;
    }

    public void setFuel(double fuel) {
        this.fuel = fuel;
    }

    public int getSeats() {
        return seats;
    }

    public Engine getEngine() {
        return engine;
    }

    public Transmission getTransmission() {
        return transmission;
    }

    public TripComputer getTripComputer() {
        return tripComputer;
    }

    public GPSNavigator getGpsNavigator() {
        return gpsNavigator;
    }
}

Concrete Product : Manual

package com.rndayala.designpatterns.builder;

/**
 * Car manual is another product. Note that it does not have the same ancestor
 * as a Car. They are not related.
 * 
 * Builder doesn’t require products to have a common interface.
 * That makes it possible to produce different products using the same construction process.
 */
public class Manual {
    private final CarType carType;
    private final int seats;
    private final Engine engine;
    private final Transmission transmission;
    private final TripComputer tripComputer;
    private final GPSNavigator gpsNavigator;

    public Manual(CarType carType, int seats, Engine engine, Transmission transmission,
                  TripComputer tripComputer, GPSNavigator gpsNavigator) {
        this.carType = carType;
        this.seats = seats;
        this.engine = engine;
        this.transmission = transmission;
        this.tripComputer = tripComputer;
        this.gpsNavigator = gpsNavigator;
    }

    public String print() {
        String info = "";
        info += "Type of car: " + carType + "\n";
        info += "Count of seats: " + seats + "\n";
        info += "Engine: volume - " + engine.getVolume() + "; mileage - " + engine.getMileage() + "\n";
        info += "Transmission: " + transmission + "\n";
        if (this.tripComputer != null) {
            info += "Trip Computer: Functional" + "\n";
        } else {
            info += "Trip Computer: N/A" + "\n";
        }
        if (this.gpsNavigator != null) {
            info += "GPS Navigator: Functional" + "\n";
        } else {
            info += "GPS Navigator: N/A" + "\n";
        }
        return info;
    }
}

Builder Interface

package com.rndayala.designpatterns.builder;

/**
 * Builder interface defines all possible ways to configure a product.
 * The interface declares all the methods to construct the complex object.
 */
public interface Builder {
    void setCarType(CarType type);
    void setSeats(int seats);
    void setEngine(Engine engine);
    void setTransmission(Transmission transmission);
    void setTripComputer(TripComputer tripComputer);
    void setGPSNavigator(GPSNavigator gpsNavigator);
}

Concrete Builder class : CarBuilder

package com.rndayala.designpatterns.builder;

/**
 * Concrete builders implements all steps defined in the common interface.
 * It provides specific implementations for constructing different parts of the complex object.
 */
public class CarBuilder implements Builder {
    private CarType type;
    private int seats;
    private Engine engine;
    private Transmission transmission;
    private TripComputer tripComputer;
    private GPSNavigator gpsNavigator;

    public void setCarType(CarType type) {
        this.type = type;
    }

    @Override
    public void setSeats(int seats) {
        this.seats = seats;
    }

    @Override
    public void setEngine(Engine engine) {
        this.engine = engine;
    }

    @Override
    public void setTransmission(Transmission transmission) {
        this.transmission = transmission;
    }

    @Override
    public void setTripComputer(TripComputer tripComputer) {
        this.tripComputer = tripComputer;
    }

    @Override
    public void setGPSNavigator(GPSNavigator gpsNavigator) {
        this.gpsNavigator = gpsNavigator;
    }

    // Concrete Builder - provides a method for retrieving the final product.
    public Car getResult() {
        return new Car(type, seats, engine, transmission, tripComputer, gpsNavigator);
    }
}

Concrete Builder class : CarManualBuilder

package com.rndayala.designpatterns.builder;

/**
 * Unlike other Creational patterns, Builder can construct unrelated products,
 * which don't have the common interface.
 *
 * In this case we build a user manual for a car, using the same steps as we
 * built a car. This allows to produce manuals for specific car models,
 * configured with different features.
 */
public class CarManualBuilder implements Builder{
    private CarType type;
    private int seats;
    private Engine engine;
    private Transmission transmission;
    private TripComputer tripComputer;
    private GPSNavigator gpsNavigator;

    @Override
    public void setCarType(CarType type) {
        this.type = type;
    }

    @Override
    public void setSeats(int seats) {
        this.seats = seats;
    }

    @Override
    public void setEngine(Engine engine) {
        this.engine = engine;
    }

    @Override
    public void setTransmission(Transmission transmission) {
        this.transmission = transmission;
    }

    @Override
    public void setTripComputer(TripComputer tripComputer) {
        this.tripComputer = tripComputer;
    }

    @Override
    public void setGPSNavigator(GPSNavigator gpsNavigator) {
        this.gpsNavigator = gpsNavigator;
    }

    public Manual getResult() {
        return new Manual(type, seats, engine, transmission, tripComputer, gpsNavigator);
    }
}

Here, we have two unrelated product classes and their builder classes. The builders of these products follow the same construction steps.

Director

The Director class uses the builder object and specifies the ordering or sequence of steps to construct the object.

package com.rndayala.designpatterns.builder;

/**
 * This Director approach is used when we want to build different unrelated products.
 * However, those products use the same object construction steps.
 * If you observe, the construction methods are not returning any object. 
 * Director only specifies the sequence of steps, but does not know what product is being built.
 * 
 * Director defines the sequence/order of building steps. It works with a builder object
 * through common Builder interface. Therefore it may not know what product is
 * being built.
 */

public class Director {

    public void constructSportsCar(Builder builder) {
    	// specifies the sequence or order of the steps
        builder.setCarType(CarType.SPORTS_CAR);
        builder.setSeats(2);
        builder.setEngine(new Engine(3.0, 0));
        builder.setTransmission(Transmission.AUTOMATIC);
        builder.setTripComputer(new TripComputer());
        builder.setGPSNavigator(new GPSNavigator());

    }

    public void constructCityCar(Builder builder) {
    	// specifies the sequence or order of the steps
        builder.setCarType(CarType.CITY_CAR);
        builder.setSeats(2);
        builder.setEngine(new Engine(1.2, 0));
        builder.setTransmission(Transmission.SEMI_AUTOMATIC);
        builder.setTripComputer(new TripComputer());
        builder.setGPSNavigator(new GPSNavigator());
    }

    public void constructSUV(Builder builder) {
    	// specifies the sequence or order of the steps
        builder.setCarType(CarType.SUV);
        builder.setSeats(4);
        builder.setEngine(new Engine(2.5, 0));
        builder.setTransmission(Transmission.MANUAL);
        builder.setTripComputer(new TripComputer());
        builder.setGPSNavigator(new GPSNavigator());
    }
}

Demo / Client code

package com.rndayala.designpatterns.builder;

/**
 * Demo class. Everything comes together here.
 */
public class Demo {

    public static void main(String[] args) {
        Director director = new Director();

        // Director gets the concrete builder object from the client
        // (application code). That's because application knows better which
        // builder to use to get a specific product.
        CarBuilder builder = new CarBuilder();
        director.constructSportsCar(builder);

        // The final product is often retrieved from a builder object, since
        // Director is not aware and not dependent on concrete builders and
        // products.
        Car car = builder.getResult();
        System.out.println("Car built:\n" + car.getCarType());


        CarManualBuilder manualBuilder = new CarManualBuilder();

        // Director may know several building recipes.
        director.constructSportsCar(manualBuilder);
        Manual carManual = manualBuilder.getResult();
        System.out.println("\nCar manual built:\n" + carManual.print());
    }

}

Builder Design Pattern implementation using Inner class

The Builder pattern is a creational design pattern that is used to construct complex objects step by step. It separates the construction of the object from its representation, allowing you to create different variations of the same object with a consistent construction process.

When using the Builder pattern with an inner class in Java, the inner class is responsible for building the complex object and accessing the private fields of the outer class. This way, the inner class can set the values of the attributes of the outer class.

Let’s create an example of a complex object called Person using the Builder pattern with an inner class:

// in this builder design pattern implementation, we are using Builder as inner class.
// the inner class has access to private instance variable of the outer class.
public class Person {
    private final String firstName; // mandatory attribute
    private final String lastName;  // mandatory attribute
    private final int age;  // optional
    private final String address;  // optional

    private Person(Builder builder) {
        this.firstName = builder.firstName;
        this.lastName = builder.lastName;
        this.age = builder.age;
        this.address = builder.address;
    }

    // Getter methods (could be omitted for brevity)

    public static class Builder {
        private final String firstName;
        private final String lastName;
        private int age;
        private String address;

        // we set the mandatory attributes using the constructor
        public Builder(String firstName, String lastName) {
            this.firstName = firstName;
            this.lastName = lastName;
        }

        // optional attributes are set using the builder methods
        public Builder age(int age) {
            this.age = age;
            return this;
        }

        public Builder address(String address) {
            this.address = address;
            return this;
        }

        // The build() method in the Builder class constructs the Person object 
        // using the private constructor of the outer class.
        public Person build() {
            return new Person(this);
        }
    }
}

// Usage
public class Main {
    public static void main(String[] args) {
        Person person1 = new Person.Builder("John", "Doe")
                .age(30)
                .address("123 Main Street")
                .build();

        Person person2 = new Person.Builder("Jane", "Smith")
                .age(25)
                .build();

        System.out.println(person1); // Person [firstName=John, lastName=Doe, age=30, address=123 Main Street]
        System.out.println(person2); // Person [firstName=Jane, lastName=Smith, age=25, address=null]
    }
}

In this example, the Person class is the complex object we want to construct. It has private fields firstName, lastName, age, and address, and a private constructor that takes a Builder object to set its attributes.

The inner class Builder provides methods to set the optional attributes of the Person object (age and address). The build() method in the Builder class constructs the Person object using the private constructor of the outer class.

By using the Builder pattern with an inner class, we can create a Person object with a clear and expressive API, specifying only the attributes we need, and leaving out the optional ones.


Use cases

Use the Builder pattern when you want your code to be able to create different representations of some product.

 The Builder pattern can be applied when construction of various representations of the product involves similar steps that differ only in the details.

same construction steps, but differ in details

The base builder interface defines all possible construction steps, and concrete builders implement these steps to construct particular representations of the product. Meanwhile, the director class guides the order of construction.

Use the Builder pattern when :

  • The algorithm for creating a complex object should be independent of the parts that
    make up the object and how they’re assembled.
  • The construction process must allow different representations for the object that’s
    constructed.

Here’s a simplified example to illustrate the components of the Builder Design Pattern:

// Product
class Car {
    private String brand;
    private String model;
    private String color;
    private int year;
    // Other attributes...

    public Car(String brand, String model, String color, int year) {
        this.brand = brand;
        this.model = model;
        this.color = color;
        this.year = year;
        // Other attribute assignments...
    }

    // Getters and other methods...
}

// Builder Interface
interface CarBuilder {
    CarBuilder setBrand(String brand);
    CarBuilder setModel(String model);
    CarBuilder setColor(String color);
    CarBuilder setYear(int year);
    Car build();
}

// Concrete Builder
class ConcreteCarBuilder implements CarBuilder {
    private String brand;
    private String model;
    private String color;
    private int year;

    public CarBuilder setBrand(String brand) {
        this.brand = brand;
        return this;
    }

    public CarBuilder setModel(String model) {
        this.model = model;
        return this;
    }

    public CarBuilder setColor(String color) {
        this.color = color;
        return this;
    }

    public CarBuilder setYear(int year) {
        this.year = year;
        return this;
    }

    public Car build() {
        return new Car(brand, model, color, year);
    }
}

// Director
class CarDirector {
    public Car buildCar(CarBuilder builder) {
        return builder.setBrand("Toyota")
                      .setModel("Corolla")
                      .setColor("Silver")
                      .setYear(2023)
                      .build();
    }
}

// Client code
public class Main {
    public static void main(String[] args) {
        CarBuilder carBuilder = new ConcreteCarBuilder();
        CarDirector director = new CarDirector();

        Car car = director.buildCar(carBuilder);
        System.out.println(car);
    }
}

In this example, the Car class represents the Product, the CarBuilder is the Builder interface, the ConcreteCarBuilder is the Concrete Builder, and the CarDirector is the Director. The Client code interacts with the Director to build the complex object using the Builder. The Builder pattern allows you to add new Concrete Builders for different types of products without modifying the Client code or the Director. This flexibility makes it easier to manage and create complex objects with many optional attributes.

Refer – https://github.com/rndayala/TechieSkills/tree/main/Java-Examples/CoreJavaExamples/src/com/rndayala/designpatterns/builder2


Another implementation – using Inner class

// Product Class - Computer
public class Computer {
    private String cpu;
    private int ram;
    private int storage;

    // Constructor (private to enforce object creation through builder)
    private Computer(String cpu, int ram, int storage) {
        this.cpu = cpu;
        this.ram = ram;
        this.storage = storage;
    }

    // Getters
    public String getCpu() {
        return cpu;
    }

    public int getRam() {
        return ram;
    }

    public int getStorage() {
        return storage;
    }

    // Inner Builder Class
    public static class ComputerBuilder {
        private String cpu;
        private int ram;
        private int storage;

        public ComputerBuilder setCPU(String cpu) {
            this.cpu = cpu;
            return this;
        }

        public ComputerBuilder setRAM(int ram) {
            this.ram = ram;
            return this;
        }

        public ComputerBuilder setStorage(int storage) {
            this.storage = storage;
            return this;
        }

        public Computer build() {
            return new Computer(cpu, ram, storage);
        }
    }
}


// Using the Builder - Application.java
public class Application {
    public static void main(String[] args) {
        Computer computer = new Computer.ComputerBuilder()
                .setCPU("Intel i7")
                .setRAM(16)
                .setStorage(512)
                .build();

        System.out.println("CPU: " + computer.getCpu());
        System.out.println("RAM: " + computer.getRam() + "GB");
        System.out.println("Storage: " + computer.getStorage() + "GB");
    }
}
  • The Computer class represents the complex object being built. It contains attributes such as the CPU, RAM, and storage.
  • The ComputerBuilder class is an inner static class within the Computer class, responsible for constructing the Computer object step by step.
  • The ComputerBuilder class provides setter methods for each attribute, allowing customization of the object being built.
  • The build() method in the ComputerBuilder class constructs and returns the final Computer object based on the configured attributes.

To build an Computer object with specific configurations, you can use the ComputerBuilder and chain the setter methods to customize the object.

Abstract Factory Design Pattern

What is an Abstract Factory Design Pattern

It’s more like factory of factories.

An abstract factory is a factory that returns factories. Why is this layer of abstraction useful? A normal factory can be used to create sets of related objects. An abstract factory returns factories. Thus, an abstract factory is used to return factories that can be used to create sets of related objects.

Abstract Factory is a creational design pattern, which solves the problem of creating entire product families without specifying their concrete classes.

** Abstract Factory defines an interface for creating all distinct products but leaves the actual product creation to concrete factory classes. Each factory type corresponds to a certain product variety.

In Abstract Factory pattern, we get rid of if-else block and have a concrete factory class for each sub-class and then an Abstract Factory class that will return the sub-class based on the input factory class.

The client code calls the creation methods of a factory object instead of creating products directly with a constructor call (new operator). Since a factory corresponds to a single product variant, all its products will be compatible.

Explanation – Understanding the pattern

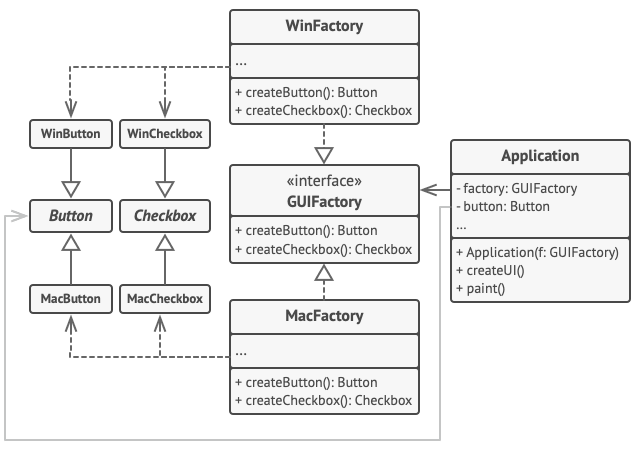
This example illustrates how the Abstract Factory pattern can be used for creating cross-platform UI elements without coupling the client code to concrete UI classes, while keeping all created elements consistent with a selected operating system.

Ref – https://refactoring.guru/design-patterns/abstract-factory

The same UI elements in a cross-platform application are expected to behave similarly, but look a little bit different under different operating systems. Moreover, it’s your job to make sure that the UI elements match the style of the current operating system. You wouldn’t want your program to render macOS controls when it’s executed in Windows.

It works like this: when an application launches, it checks the type of the current operating system. The app uses this information to create a factory object from a class that matches the operating system. The rest of the code uses this factory to create UI elements. This prevents the wrong elements from being created.

The Abstract Factory interface declares a set of creation methods that the client code can use to produce different types of UI elements. Concrete factories correspond to specific operating systems and create the UI elements that match that particular OS.

Benefits

  • Abstract Factory pattern provides approach to code for interface rather than
    implementation.
  • Abstract Factory pattern is “factory of factories” and can be easily extended to
    accommodate more products, for example we can easily add Material theme product family.
  • Abstract Factory pattern is robust and avoid conditional logic of Factory pattern.

When to use: A family of related product objects is designed to be used together, and you need to enforce this constraint.

Examples

Usage examples: The Abstract Factory pattern is pretty common in Java code. Many frameworks and libraries use it to provide a way to extend and customize their standard components.

Here are some examples from core Java libraries:

Identification: The pattern is easy to recognize by methods, which return a factory object. Then, the factory is used for creating specific sub-components.

Implementation

In our example, we create families of cross-platform GUI components and their production. The components, buttons and checkboxes will act as products. They have two variants: macOS and Windows.

The abstract factory defines an interface for creating buttons and checkboxes. There are two concrete factories, which return both products in a single variant.

Client code works with factories and products using abstract interfaces. It makes the same client code working with many product variants, depending on the type of factory object.

buttons: First product hierarchy

Button.java

package com.rndayala.designpatterns.abstractfactory;

/**
 * Abstract Factory assumes that you have several families of products,
 * structured into separate class hierarchies (Button/Checkbox). All products of
 * the same family have the common interface.
 *
 * This is the common interface for buttons family.
 */
public interface Button {
    void render();
}

MacOSButton.java

package com.rndayala.designpatterns.abstractfactory;

/**
 * All products families have the same varieties (MacOS/Windows).
 *
 * This is a MacOS variant of a button.
 */
public class MacOSButton implements Button {

    @Override
    public void render() {
        System.out.println("You have created MacOSButton.");
    }
}

WindowsButton.java

package com.rndayala.designpatterns.abstractfactory;

/**
 * All products families have the same varieties (MacOS/Windows).
 *
 * This is another variant of a button.
 */
public class WindowsButton implements Button {

    @Override
    public void render() {
        System.out.println("You have created WindowsButton.");
    }
}

checkboxes: Second product hierarchy

Checkbox.java

package com.rndayala.designpatterns.abstractfactory;

/**
 * Checkboxes is the second product family. It has the same variants as buttons.
 */
public interface Checkbox {
    void render();
}

MacOSCheckbox.java

package com.rndayala.designpatterns.abstractfactory;

/**
 * All products families have the same varieties (MacOS/Windows).
 *
 * This is a variant of a checkbox.
 */
public class MacOSCheckbox implements Checkbox {

    @Override
    public void render() {
        System.out.println("You have created MacOSCheckbox.");
    }
}

WindowsCheckbox.java

package com.rndayala.designpatterns.abstractfactory;

/**
 * All products families have the same varieties (MacOS/Windows).
 *
 * This is another variant of a checkbox.
 */
public class WindowsCheckbox implements Checkbox {

    @Override
    public void render() {
        System.out.println("You have created WindowsCheckbox.");
    }
}

Abstract factory : GUIFactory.java

package com.rndayala.designpatterns.abstractfactory;

/**
 * Abstract factory knows about all (abstract) product types.
 * It declares a set of creation methods for product types.
 */
public interface GUIFactory {
    Button createButton();
    Checkbox createCheckbox();
}

MacOSFactory.java: Concrete factory (macOS)

package com.rndayala.designpatterns.abstractfactory;

/**
 * Each concrete factory extends basic factory and responsible for creating
 * products of a single variety.
 */
public class MacOSFactory implements GUIFactory {

    @Override
    public Button createButton() {
        return new MacOSButton();
    }

    @Override
    public Checkbox createCheckbox() {
        return new MacOSCheckbox();
    }
}

WindowsFactory.java: Concrete factory (Windows)

package com.rndayala.designpatterns.abstractfactory;

/**
 * Each concrete factory extends basic factory and responsible for creating
 * products of a single variety.
 */
public class WindowsFactory implements GUIFactory {

    @Override
    public Button createButton() {
        return new WindowsButton();
    }

    @Override
    public Checkbox createCheckbox() {
        return new WindowsCheckbox();
    }
}

Client code : Application.java

package com.rndayala.designpatterns.abstractfactory;

/**
 * Factory users don't care which concrete factory they use since they work with
 * factories and products through abstract interfaces.
 */
public class Application {
    private Button button;
    private Checkbox checkbox;

    public Application(GUIFactory factory) {
        button = factory.createButton();
        checkbox = factory.createCheckbox();
    }

    public void render() {
        button.render();
        checkbox.render();
    }
}

App configuration : Demo.java

package com.rndayala.designpatterns.abstractfactory;

/**
 * Demo class. Everything comes together here.
 */
public class Demo {

    /**
     * Application picks the factory type and creates it in run time (usually at
     * initialization stage), depending on the configuration or environment
     * variables.
     */
    private static Application configureApplication() {
        Application app;
        GUIFactory factory;
        String osName = System.getProperty("os.name").toLowerCase();
        if (osName.contains("mac")) {
            factory = new MacOSFactory();
        } else {
            factory = new WindowsFactory();
        }
        app = new Application(factory);
        return app;
    }

    public static void main(String[] args) {
        Application app = configureApplication();
        app.render();
    }
}

Ref : https://refactoring.guru/design-patterns/abstract-factory


Use cases

  • Use the Abstract Factory when your code needs to work with various families of related products, but you don’t want it to depend on the concrete classes of those products—they might be unknown beforehand or you simply want to allow for future extensibility.
  • The Abstract Factory provides you with an interface for creating objects from each class of the product family. As long as your code creates objects via this interface, you don’t have to worry about creating the wrong variant of a product which doesn’t match the products already created by your app.


Factory Design Pattern

What is a Factory Design Pattern

Factory design pattern is used when we have a super class with multiple sub-classes and based on input, we need to return one of the sub-classes.

This pattern takes out the responsibility of instantiation of a class from client program to the factory class. We can apply Singleton pattern on Factory class or make the factory method static.

Super class in factory pattern can be an interface or a normal java class.

Explanation

The Factory design pattern is a way of creating objects in an object-oriented programming language.

Imagine you have a car factory. The factory makes cars. When you order a car, you specify the type of car you want (e.g. sedan, SUV, sports car, etc.). The factory then builds the car for you and delivers it to you.

Similarly, in the Factory design pattern, you have a factory class that creates objects of different types. When you ask the factory to create an object, you specify the type of object you want. The factory then creates the object for you and returns it to you.

This allows you to separate the process of creating objects from the rest of your code, making it easier to change the way objects are created if needed.

Think of the factory as a kind of “object-making machine.” Instead of writing code to create objects, you tell the factory what you want, and it creates the objects for you. This makes your code easier to read and maintain, and makes it easier to change how objects are created if needed.


The Factory design pattern is often used in situations where client code cannot anticipate the type of objects it needs to create.

The Factory design pattern provides several benefits:

• Abstraction: It separates the implementation details of object creation from the client code, allowing the client code to focus on the task at hand and not the details of object creation.

• Flexibility: The Factory design pattern allows you to add new types of objects to your application without having to modify the client code. This makes it easier to maintain and extend your application.

• Reusability: By encapsulating the details of object creation in a factory class, you can reuse the factory in multiple parts of your application, making your code more modular and easier to maintain. Overall, the Factory

Benefits

  • Factory pattern provides approach to code for interface rather than implementation.
  • Factory pattern removes the instantiation of actual implementation classes from client
    code
    , making it more robust, less coupled and easy to extend.
  • Factory pattern provides abstraction between implementation and client classes through inheritance.

Examples

  • java.util.Calendar, ResourceBundle, java.text.DateFormat and java.text.NumberFormat getInstance () methods uses Factory pattern.
  • valueOf () method in wrapper classes like Boolean, Integer etc.

the Calendar class utilizes the Factory Method getInstance() to create instances of the Calendar class based on the user’s default locale and timezone. The getInstance() method is static, and it internally determines which specific implementation of Calendar to return based on the locale and timezone settings.

// Get an instance of the default Gregorian calendar
Calendar gregorianCalendar = Calendar.getInstance();
System.out.println("Default Calendar: " + gregorianCalendar.getClass().getName());

// Get an instance of a different calendar system (e.g., Buddhist)
Calendar buddhistCalendar = Calendar.getInstance(java.util.Locale.forLanguageTag("th-TH"));
System.out.println("Buddhist Calendar: " + buddhistCalendar.getClass().getName());

Implementation

It allows the client code to create objects by delegating the responsibility of object instantiation to a factory class.

package com.rndayala.designpatterns.factory;

// interface that defines common functionality to be 
// implemented by all related types
public interface Shape {
	void draw();
}

// Concrete class that implements the functionality provided by interface
public class Circle implements Shape {
	@Override
	public void draw() {
		System.out.println("Inside Circle::draw() method."); 

	}
}

// Concrete Product classes implementing the Shape interface
public class Rectangle implements Shape {
	@Override
	public void draw() {
		System.out.println("Inside Rectangle::draw() method."); 
	}
}

// Concrete Product classes implementing the Shape interface
public class Square implements Shape {
	@Override
	public void draw() {
		System.out.println("Inside Square::draw() method."); 

	}
}

Then you define a Factory class that does the instantiation of object based on the type.

package com.rndayala.designpatterns.factory;

// Simple Factory class responsible for creating Shape objects
public class FactoryClass {
	
	// static Factory method which instantiates the object and returns to client 
	public static Shape getShape(String shapeType) {
		if (shapeType == null) {
			return null;
		}

		if (shapeType.equalsIgnoreCase("CIRCLE")) {
			return new Circle();
		} else if (shapeType.equalsIgnoreCase("RECTANGLE")) {
			return new Rectangle();
		} else if (shapeType.equalsIgnoreCase("SQUARE")) {
			return new Square();
		} else if (shapeType.equalsIgnoreCase("TRIANGLE")) {
			// TODO : Add Triangle class which implements Shape interface
		}
		return null;
	}
}

Client code that uses the Factory class :

package com.rndayala.designpatterns.factory;

public class FactoryTest {

	public static void main(String[] args) {
		// create objects of  the Shape interface by calling the getShape method 
		// and passing the appropriate String argument. 
		// Type of object to create is determined at runtime by user.
		// NOTE - We code against interface. Higher level modules doesn't depend on lower level classes. 
		Shape shape = FactoryClass.getShape("Circle");
		shape.draw();
		
		shape = FactoryClass.getShape("Square");
		shape.draw();
		
		shape = FactoryClass.getShape("Rectangle");
		shape.draw();
	}
}

Implementations of the Factory Design Pattern in Java provide a way to encapsulate object creation, allowing the client code to focus on using the objects rather than being concerned with how they are created.


Simple Factory Method

In the simple factory method, a separate factory class is responsible for creating instances of various concrete classes that share a common superclass or interface.

// Interface for the Product objects
interface Product {
    void doSomething();
}

// Concrete Product classes implementing the Product interface
class ConcreteProductA implements Product {
    public void doSomething() {
        System.out.println("Doing something in ConcreteProductA.");
    }
}

class ConcreteProductB implements Product {
    public void doSomething() {
        System.out.println("Doing something in ConcreteProductB.");
    }
}

// Simple Factory class responsible for creating Product objects
class ProductFactory {

    // static factory method
    public static Product createProduct(String type) {
        switch (type) {
            case "A":
                return new ConcreteProductA();
            case "B":
                return new ConcreteProductB();
            default:
                throw new IllegalArgumentException("Invalid product type: " + type);
        }
    }
}

// Client code
public class Main {
    public static void main(String[] args) {
        Product productA = ProductFactory.createProduct("A");
        productA.doSomething(); // Output: Doing something in ConcreteProductA.

        Product productB = ProductFactory.createProduct("B");
        productB.doSomething(); // Output: Doing something in ConcreteProductB.
    }
}

Implementations of the Factory Design Pattern in Java provide a way to encapsulate object creation, allowing the client code to focus on using the objects rather than being concerned with how they are created.


Use cases

Some common use cases of the Factory Pattern include:

  • When a class cannot anticipate the type of objects it needs to create
  • When a class wants its subclasses to specify the objects it creates
  • When classes delegate responsibility to one of several helper subclasses, and you want to localize the knowledge of which helper subclass is the delegate.

Examples of situations where the Factory Pattern can be used include:

  • when creating objects for UI elements, such as buttons or panels, based on user input or configuration data
  • when implementing a plugin architecture where objects of different types can be created based on user-selected options
  • when managing the creation of objects that are part of a larger system, such as creating database connections based on configuration data.

Singleton Design Pattern

What is a Singleton Design Pattern

Sometimes it’s important for some classes to have exactly one instance. There are many objects we only need one instance of them and if we, instantiate more than one, we’ll run into all sorts of problems like incorrect program behavior, overuse of resources, or inconsistent results.

There are only two points in the definition of a singleton design pattern,

  • There should be only one instance allowed for a class and
  • We should allow global point of access to that single instance.

From the definition, it seems to be a very simple design pattern but when it comes to
implementation, it comes with a lot of implementation concerns.

Explanation of the pattern

With the Singleton pattern, you define a private constructor in the class, which ensures that no one can create a new instance of the class from outside. You also define a public method called “getInstance” that returns the single instance of the class.

The first time the method is called, it creates a new instance of the class. Any subsequent calls to the method return the same instance that was created the first time. In this way, you ensure that there is only one instance of the class.

The Singleton pattern can be implemented in various ways, but it is essential to ensure that only one instance of the class is created, and that it is accessible from anywhere in the code. To achieve this, it is common to use lazy initialization, where the instance is created only when it is first needed.

In summary, the Singleton pattern can be useful for creating shared resources in a system where it is important to maintain a single instance and ensure that it is accessible from anywhere in the code. It can also be used to control the instantiation of a class, ensuring that it is only created once, and to provide a single point of access to the instance.

Why Lazy Initialization

Lazy initialization will be beneficial when we want to delay the initialization until it is not
needed, because if we use eager initialization and if initialization fails there is no chance
to get the instance further. While in lazy initialization we may get it in second chance. In Lazy initialization we will not get instance until we call getInstance () method while in
eager initialization it creates instance at the time of class loading.


How to implement Singleton pattern

package com.rndayala.designpatterns.singleton;

// Author : Raghunath Dayala

/* Singleton is a design pattern that restricts a class to have ONLY one instance, 
 * with a global point of access to it.
 * Useful when you want to limit the number of instances of a class that can exist in the system.
 * This can be useful in situations  where you want to maintain a single instance of a class 
 * to represent a shared resource, such as a  logging service, database connection or a configuration manager.
 * Ref : Check my Kindle library
 */

public class Singleton {
	// private static variable
	private static Singleton instance = null;
	
	// a private constructor that ensures that it cannot be instantiated directly from outside the class.
	private Singleton() {
		System.out.println("Creating Singleton class object..");
	}
	
	// public static method called getInstance is provided, 
	// which returns the  single instance of the class.  
	// The first time the getInstance is invoked, it creates and returns the object.
	// Any subsequent calls returns the same instance created the first time.
	public static Singleton getInstance() {
		if (instance == null) {
			instance = new Singleton();
		}
		return instance;
	}
}

/* Problems :
 * 1. the above implementation is not thread safe.
 * 2. We can still be able to create new objects using Reflection.
 * 3. We can be able to create new objects using Cloning.
 * 4. When we do serialization/de-serialization, we get new objects.
*/

In above example, the Singleton class has a private constructor that ensures that it cannot be instantiated directly. Instead, a public static method called getInstance is provided, which returns the single instance of the class.

The first time the getInstance method is called, it creates a new instance of the Singleton class by calling the private constructor. Subsequent calls to getInstance return the same instance that was created the first time.

Multi-threaded Singleton implementation

Singleton will work properly in multithreaded environment only if eager instantiation has been done because in this case instance creation will happen at the time of class loading only. But for Lazy instantiation we will have to take care of multiple things. If we want to delay the instantiation because of cost, we use to go with lazy.

Simple Implementation :

package com.rndayala.designpatterns.singleton;

/**
 * Singleton in multi-threaded environments.
 * the behavior of Singleton instance when two threads are 
 * getting executed by comparing their hash code values.
 * 
 * The following code works only in Java 8.
 * @author rndayala
 */

import java.util.concurrent.ExecutorService;
import java.util.concurrent.Executors;

public class SingletonT {
	
	private static SingletonT instance = null; // lazy initialization
	
	private SingletonT() {
		System.out.println("Creating..");
	}
	
	// When you run the above program many times you will notice that in multithreaded environment,
	// sometimes Singleton principle works, but sometimes it violates.

	public static SingletonT getInstance() {
		if (instance == null) {
			instance = new SingletonT();
		}
		return instance;
	}


	static void useSingleton() {
		SingletonT singleton = SingletonT.getInstance();
		print("Singleton", singleton);
	}
	
	static void print(String name, SingletonT obj) {
		System.out.println(String.format("Object : %s, hashcode : %d", name, obj.hashCode()));
	}
	
	public static void main(String[] args) {
		ExecutorService service = Executors.newFixedThreadPool(2);
		service.submit(SingletonT::useSingleton); // Object : Singleton, hashcode : 918401706
		service.submit(SingletonT::useSingleton); // Object : Singleton, hashcode : 918401706
		service.shutdown();
	}

}

/* observations :
 * When you run the above program many times you will notice that in multithreaded environment,
 * sometimes Singleton principle works but sometimes it violates.
 * Fix : After applying synchronized keyword in the getInstance () method, the program will execute 
 * properly without any issue but in Java.
*/

When you run the above program many times you will notice that in multithreaded environment, sometimes Singleton principle works, but sometimes it violates. Therefore we need to synchronize the getInstance () method as shown below :

	// When you run the above program many times you will notice that in multithreaded environment,
	// sometimes Singleton principle works, but sometimes it violates.
	// Fix : add synchronized keyword to the getInstance() method

	public static synchronized SingletonT getInstance() {
		if (instance == null) {
			instance = new SingletonT();
		}
		return instance;
	}

After applying synchronized keyword in the getInstance () method the program will execute properly without any issue.


Double Checked Locking

Instead of synchronizing whole method we can synchronize only the block of code which is affected while creating instance to escape the extra overhead as below :

	// Don't synchronize getInstance() method completely.
	// Synchronize only the block of code which is affected while creating instance.
	public static SingletonT getInstance() {
		if (instance == null) {
			synchronized (SingletonT.class) {
				instance = new SingletonT();
			}
		}
		return instance;
	}

From the above code we have narrowed down the scope of synchronization for performance reasons. But the above code can cause issues due to thread switching.

So to make sure no other thread has already acquired the lock we will apply one more check after acquiring the lock as shown below. This method is called Double Checked Locking.

	// Don't synchronize getInstance() method completely.
	// Synchronize only the block of code which is affected while creating instance.
	public static SingletonT getInstance() {
		if (instance == null) {
			synchronized (SingletonT.class) {
				// double checked locking
				if (instance == null) {
					instance = new SingletonT();
				}
			}
		}
		return instance;
	}

Sometimes double checked locking also breaks the Principle of Singleton. It may return an instance in half-initialized state.

To address this situation use volatile keyword at the time of instance declaration. Value of volatile variable will be published only when the change completes. Change to write
operation happens before read operation in volatile variable. In short all threads will see the same value of variable.

private static volatile SingletonT instance = null; // lazy initialization

Reflection – Singleton implementation violation ? How to Fix ?

In Java, you can violate the Singleton pattern’s intended behavior using reflection.

Reflection allows you to access and modify the private constructors and fields of a class, which can lead to the creation of multiple instances of the Singleton class, thus violating the pattern.

Here’s an example of how the Singleton pattern can be violated using reflection in Java:

import java.lang.reflect.Constructor;

public class Singleton {

    private static Singleton instance;

    private Singleton() {
        // Private constructor
    }

    public static Singleton getInstance() {
        if (instance == null) {
            instance = new Singleton();
        }
        return instance;
    }

    // Other methods and fields...
}

public class Main {

    public static void main(String[] args) {
        Singleton singleton1 = Singleton.getInstance();
        Singleton singleton2 = null;

        try {
            // Using reflection to access the private constructor
            Constructor<Singleton> constructor 
                              = Singleton.class.getDeclaredConstructor();
            constructor.setAccessible(true);
            singleton2 = constructor.newInstance();
        } catch (Exception e) {
            e.printStackTrace();
        }

        System.out.println(singleton1); // Output: Singleton@hashcode1
        System.out.println(singleton2); // Output: Singleton@hashcode2
    }
}

In the example above, we try to access the private constructor of the Singleton class using reflection and create a new instance. As a result, singleton2 is not the same instance as singleton1, and we have violated the Singleton pattern’s intent.

To protect against this kind of reflection-based Singleton pattern violation, you can modify the Singleton class to throw an exception if someone tries to create a new instance using reflection:

public class Singleton {

    private static Singleton instance;

    private Singleton() {
        if (instance != null) {
            throw new RuntimeException("Use getInstance() method to get the single instance.");
        }
    }

    public static Singleton getInstance() {
        if (instance == null) {
            instance = new Singleton();
        }
        return instance;
    }

    // Other methods and fields...
}

By adding the check inside the private constructor, any attempt to create a new instance through reflection will result in an exception, preserving the Singleton pattern’s integrity. However, it’s essential to be cautious when using reflection and design patterns together, as it can lead to unexpected behavior and undermine the patterns’ intended benefits.

Clone – Singleton implementation violation ? How to Fix ?

If we try to make instance by cloning it, the generated hash code of cloned
copy doesn’t match with the actual object so it also violates the Singleton principle of having a single instance.

Here’s an example to illustrate the issue:

public class Singleton implements Cloneable {

    private static Singleton instance;

    private Singleton() {
        // Private constructor
    }

    public static Singleton getInstance() {
        if (instance == null) {
            instance = new Singleton();
        }
        return instance;
    }

    @Override
    protected Object clone() throws CloneNotSupportedException {
        return super.clone();
    }

    // Other methods and fields...
}

public class Main {

    public static void main(String[] args) {
        Singleton singleton1 = Singleton.getInstance();
        Singleton singleton2 = null;

        try {
            // Cloning the singleton object
            singleton2 = (Singleton) singleton1.clone();
        } catch (CloneNotSupportedException e) {
            e.printStackTrace();
        }

        System.out.println(singleton1); // Obj: singleton1, hashcode: 366712642
        System.out.println(singleton2); // Obj: clone, hashcode: 1442407170
    }
}

In this example, we implement the Cloneable interface in the Singleton class, and we override the clone() method to call the super.clone() method. The generated hash code of cloned copy doesn’t match with the actual object so it also violates the Singleton principle.

To address this issue, you may consider throwing an exception in the clone() method to prevent cloning altogether:

public class Singleton implements Cloneable {

    // Singleton implementation...

    @Override
    protected Object clone() throws CloneNotSupportedException {
        throw new CloneNotSupportedException("Cloning of Singleton objects is not allowed.");
    }

    // Other methods and fields...
}

By throwing a CloneNotSupportedException, you explicitly prohibit cloning of the Singleton objects and maintain the integrity of the Singleton pattern. However, it’s important to note that the use of Cloneable and clone() method can be controversial in Java, and it is generally recommended to avoid using them in favor of other approaches like copy constructors or factory methods for object duplication.

How to fix: Throw CloneNotSupportedException from the clone () method if someone
tries to make other instance of it.


Bill Pugh method – Singleton Implementation

The Bill Pugh Singleton pattern, also known as the Initialization-on-demand Holder Idiom, is an improvement over the traditional Singleton pattern.

It provides a simpler and more thread-safe way to implement a Singleton in Java without the need for explicit synchronization. This pattern takes advantage of the Java class-loading mechanism to ensure that the Singleton instance is created lazily and safely when the class is loaded.

We use inner static class approach in this implementation. The inner static class encapsulates the Singleton instance, and its instantiation logic is taken care of by the JVM, reducing the need for explicit synchronization or volatile variables.

Bill Pugh implementation – thread safe, no need of explicit synchronization or volatile variable. The inner static class shields the Singleton instance from being created through reflection, as the constructor remains private.

Here’s the implementation of the Bill Pugh Singleton pattern:

public class Singleton {

    // Private constructor to prevent instantiation from other classes
    private Singleton() {
        // Initialization code (if any) goes here
    }

    // Inner static helper class responsible for holding the Singleton instance
    private static class SingletonHolder {
        // The Singleton instance is created when the class is loaded
        private static final Singleton INSTANCE = new Singleton();
    }

    // Public static method to get the Singleton instance
    public static Singleton getInstance() {
        return SingletonHolder.INSTANCE;
    }

    // Other methods and fields...
}

In this implementation, the Singleton class has a private constructor to prevent direct instantiation. The Singleton instance is stored as a static field within a nested static class called SingletonHolder. The INSTANCE field is initialized during the class-loading phase, which is guaranteed to be thread-safe by the Java Virtual Machine.

When getInstance() is called, it returns the Singleton instance held by the SingletonHolder, ensuring that only one instance is created throughout the application’s lifecycle.

Here’s how you can use the Bill Pugh Singleton pattern:

public class Main {

    public static void main(String[] args) {
        // Get the Singleton instance
        Singleton singleton1 = Singleton.getInstance();
        Singleton singleton2 = Singleton.getInstance();

        // Both instances are the same
        System.out.println(singleton1 == singleton2); // Output: true
    }
}

This approach provides better performance and avoids unnecessary synchronization overhead because the Singleton is initialized lazily and only when needed.

Nowadays, this Bill Pugh method is widely used and considered a best practice for creating Singleton instances.


enum implementation of Singleton pattern

In Java, you can implement the Singleton pattern using an enum.

Enums in Java are implicitly singleton by design, as they only allow a fixed set of predefined instances, and there can be no more than one instance of each enum constant. This property makes enums a natural fit for implementing a singleton.

Joshua Bloch suggests the use of Enum to implement Singleton design pattern as Java ensures that any enum value is instantiated only once in a Java program. Since Java Enum values are globally accessible, so is the singleton.

The drawback is that the enum type is somewhat inflexible; for example, it does not allow lazy initialization.

Here’s how you can implement the Singleton pattern using an enum :

public enum SingletonEnum {
    INSTANCE;

    // Any additional fields or methods for the Singleton can be added here
    // ...

    // Example method
    public void doSomething() {
        // Implement functionality here
    }
}

In this implementation, SingletonEnum is an enum that contains a single instance called INSTANCE. When the SingletonEnum class is loaded, the INSTANCE constant is initialized, and it remains the only instance throughout the application’s lifecycle.

In the context of implementing the Singleton pattern using an enum, the INSTANCE is a single constant instance of the enum type. In Java, enum constants are implicitly static and final, which means they can only be created once during the class loading and cannot be modified afterward. As a result, an enum with a single constant effectively serves as a singleton.

INSTANCE represents the sole instance of the SingletonEnum class. The enum constant name (INSTANCE in this case) can be any valid Java identifier, but by convention, INSTANCE is commonly used to signify that it represents the single instance of the singleton.

You can use the SingletonEnum instance like this:

public class Main {

    public static void main(String[] args) {
        SingletonEnum singleton1 = SingletonEnum.INSTANCE;
        SingletonEnum singleton2 = SingletonEnum.INSTANCE;

        // Both instances are the same
        System.out.println(singleton1 == singleton2); // Output: true

        // Call methods on the Singleton instance
        singleton1.doSomething();
    }
}

As enum constants are inherently thread-safe and guaranteed to be initialized only once, using an enum for the Singleton pattern eliminates the need for explicit synchronization and ensures a simple, efficient, and safe singleton implementation in Java.

As with any enum, the SingletonEnum’s instance is implicitly thread-safe and immune to issues related to reflection or serialization, making this approach one of the simplest and most effective ways to implement a thread-safe Singleton pattern in Java.

Enum Singleton doesn’t violate principle of Singleton in any case described above.

Design Patterns Introduction

What are Design Patterns

A design pattern is a reusable solution to a commonly occurring problem in software design. It represents a general, proven approach that can be applied to various situations to address specific design challenges.

The design patterns are language independent strategies for solving common object-oriented design problems.

Design patterns are an essential tool for software development that can help programmers write more organized, efficient, and reusable code.

They are like pre-made templates for solving common problems that arise in software development, offering a standardized and proven solution for each problem. By using design patterns, programmers can save time, reduce the risk of bugs, and improve the overall quality of their code.


They are usually divided into categories such as creational, structural, and behavioral patterns, each with its own unique set of solutions.

By learning design patterns in Java, developers can deepen their understanding of object-oriented concepts and improve their ability to design and implement complex software.


Why learn Design Patterns

When you make a design, you should know the names of some common solutions. Learning design patterns is good for people to communicate each other effectively.

SUN suggests GOF (Gang of Four—four pioneer guys who wrote a book named
“Design Patterns”- Elements of Reusable Object-Oriented Software), so we use that book as our guide to describe solutions.

Design patterns are an essential tool for software development that can help programmers write more organized, efficient, and reusable code.

They are like pre-made templates for solving common problems that arise in software development, offering a standardized and proven solution for each problem. By using design patterns, programmers can save time, reduce the risk of bugs, and improve the overall quality of their code.


Categories of Design Patterns

Design patterns are generally categorized into three main types:

1. Creational Patterns: These patterns are used to create objects and classes in a way that is suitable for a particular situation. Creational design patterns provide solution to instantiate an object in the best possible way for specific situations.

  • Singleton Pattern
  • Factory Pattern
  • Abstract Factory Pattern
  • Builder Pattern
  • Prototype Pattern

2. Structural Patterns: These patterns are used to arrange classes and objects to form larger structures. Structural patterns provide different ways to create a class
structure, for example using inheritance and composition to create a large object from
small objects.

  • Adapter Pattern
  • Composite Pattern
  • Proxy Pattern
  • Flyweight Pattern
  • Facade Pattern
  • Bridge Pattern
  • Decorator Pattern

3. Behavioral Patterns: These patterns are used to describe the ways in which objects interact and communicate with each other. Behavioral patterns provide solution for the better interaction between objects and how to provide lose coupling and flexibility to extend easily.

  • Template Method Pattern
  • Mediator Pattern
  • Chain of Responsibility Pattern
  • Observer Pattern
  • Strategy Pattern
  • Command Pattern
  • State Pattern
  • Visitor Pattern
  • Iterator Pattern
  • Interpreter Pattern
  • Memento Pattern

These categorizations are a useful way to understand the different types of design patterns and their intended uses.

JUnit

What is JUnit ?

JUnit is a widely used open-source testing framework for Java programming language. It provides a set of annotations and assertions to write and execute unit tests for Java applications.

  • Unit testing is a software testing method where individual units of code, such as methods or classes, are tested to ensure they function correctly in isolation.

JUnit facilitates the creation and execution of automated tests by providing a framework that simplifies test case creation and test result verification. It follows the principles of test-driven development (TDD) and encourages developers to write tests before implementing the corresponding functionality. This approach helps improve code quality, maintainability, and reliability.

Some key features of JUnit include:

  1. Annotations: JUnit uses annotations, such as @Test, to mark test methods within test classes. These annotations provide instructions to JUnit on how to execute the tests.
  2. Assertions: JUnit provides a wide range of assertion methods to verify expected outcomes. These assertions help compare actual values with the expected values to determine if the test passes or fails.
  3. Test Runners: JUnit utilizes test runners to discover and execute tests. Test runners are responsible for managing the execution of test cases and reporting the results.
  4. Test Fixtures: JUnit allows the setup and teardown of test fixtures using annotations like @Before, @After, @BeforeClass, and @AfterClass. These annotations enable the execution of specific methods before and after each test or before and after the entire test class.

JUnit has become the de facto standard for unit testing in Java. It integrates well with various development environments, build tools, and continuous integration systems. With JUnit, developers can easily write and execute tests to validate the behavior of their code, ensuring its correctness and stability.

JUnit Maven Dependency

To use JUnit in a Maven project, you need to add the JUnit dependency to your project’s pom.xml file. Here’s an example of how to include the JUnit dependency in your Maven project:

<dependencies>
  <dependency>
    <groupId>junit</groupId>
    <artifactId>junit</artifactId>
    <version>4.13.2</version>
    <scope>test</scope>
  </dependency>
</dependencies>

In the above example, the dependency element specifies the details of the JUnit dependency. The groupId is set to “junit,” the artifactId is set to “junit,” and the version is set to “4.13.2,” which is the latest version at the time of writing. The <scope>test</scope> ensures that JUnit is only used for testing purposes and is not included in the runtime classpath.

Once you’ve added the dependency to your pom.xml file, Maven will automatically download the JUnit JAR file and its dependencies from the Maven Central Repository when you build your project. You can then use JUnit in your tests by importing the necessary classes and annotations in your test classes.

How to write a simple test case using JUnit ?

To write a simple test case in JUnit, you can follow these steps:

  1. Create a new Java class for your test case. This class should be separate from your application code and typically resides in a test source directory (src\test\java\ – java source code for tests).
  2. Import the necessary JUnit classes and annotations. The commonly used ones are org.junit.Test for marking test methods and org.junit.Assert for assertion methods.
  3. Create a test method and annotate it with @Test. This annotation tells JUnit that this method should be executed as a test case.
  4. Write the code to set up any necessary test data or objects.
  5. Use the assertion methods from Assert class to verify the expected results. JUnit provides various assertion methods like assertEquals(), assertTrue(), assertFalse(), etc.
  6. Optionally, you can use other JUnit annotations like @Before and @After to define setup and teardown methods that run before and after each test method.

Here’s an example of a simple JUnit test case:

import org.junit.Test;
import static org.junit.Assert.*;

public class MyTestCase {

    @Test
    public void testAddition() {
        int result = add(2, 3);
        assertEquals(5, result);
    }

    @Test(expected = IllegalArgumentException.class)
    public void testDivideByZero() {
        divide(10, 0);
    }

    private int add(int a, int b) {
        return a + b;
    }

    private int divide(int dividend, int divisor) {
        if (divisor == 0) {
            throw new IllegalArgumentException("Divisor cannot be zero");
        }
        return dividend / divisor;
    }
}

The @Test annotation is a key annotation provided by JUnit. It is used to mark a method as a test case that should be executed by the test runner. When JUnit encounters a method annotated with @Test, it considers it as a test case and executes it during the testing process.

Here are some important aspects of the @Test annotation:

  1. Execution: Methods annotated with @Test are executed by the JUnit test runner. Each method annotated with @Test is treated as an independent test case and is executed in isolation.
  2. Signature: The test method should be public, return void, and not take any parameters. It is generally named descriptively to indicate the functionality being tested.
  3. Assertions: Test methods typically contain assertions to verify the expected behavior of the code being tested. These assertions are used to compare the actual results with the expected results.
  4. Expected exceptions: You can specify an expected exception using the expected attribute of the @Test annotation. If the specified exception is thrown during the execution of the test method, the test will pass. If the exception is not thrown or a different exception is thrown, the test will fail.

In the above example, the testAddition() method is marked with @Test and verifies the addition of two numbers.

The testDivideByZero() method is also marked with @Test and specifies that it expects an IllegalArgumentException to be thrown when dividing by zero.

By using the @Test annotation, you can easily identify and execute specific methods as test cases during the test execution.

Naming conventions for test methods in JUnit

When writing test methods in JUnit, it is beneficial to follow naming conventions that provide clarity and consistency. Although JUnit does not enforce any specific naming conventions for test methods, using a standard naming approach can enhance the readability and understandability of your test suite.

Here are some common naming conventions for writing test methods in JUnit:

  1. Method Name Format: It is typical to prefix the name of each test method with the word “test” to indicate that it is a test case. For example, testMethodName().
  2. Descriptive Names: Use descriptive names that convey the purpose or behavior being tested. A good test method name should describe the scenario being tested and the expected outcome. This helps others understand the intent of the test without needing to examine the test code in detail.
  3. Clarity and Readability: Make the test method names concise, clear, and easy to read. Avoid ambiguous or overly complex names that can lead to confusion.
  4. CamelCase Convention: Follow the standard Java naming convention of using camel case for method names. Begin each word after the first with an uppercase letter, for example, testAddition() or testCalculateDiscount().
  5. Use Action-Outcome Style: Structure the test method names in an action-outcome style, where the name reflects the action being performed and the expected outcome. For example, testSaveUserSuccessfully() or testInvalidInputValidation().
  6. Use Underscores for Clarity: If needed, you can use underscores to improve the readability of long test method names. For example, test_calculate_discount_for_large_order().

Remember, the primary goal is to make the test method names self-explanatory and understandable without having to inspect the implementation details. Adopting a consistent naming convention throughout your test suite can enhance maintainability and collaboration among team members.

Ultimately, choose a naming convention that aligns with your project’s coding standards and promotes clarity and consistency in your tests.


Understanding @Before and @After annotations

The @Before and @After annotations are provided by JUnit to perform setup and teardown operations before and after each test method execution. These annotations allow you to define methods that will be executed automatically by the test runner, helping you set up the necessary environment for your tests and clean up any resources afterward.

Here’s an explanation of the @Before and @After annotations:

  1. @Before:
    • Annotating a method with @Before indicates that it should be executed before each test method.
    • The purpose of @Before is to set up the preconditions or initialize any necessary objects or resources that are common across multiple test methods.
    • Methods annotated with @Before are commonly used to create test objects, set up test data, establish database connections, or initialize other dependencies required for the test.
    • If multiple methods are annotated with @Before, they will be executed in the order they are declared.
  1. @After:
    • Annotating a method with @After indicates that it should be executed after each test method.
    • The purpose of @After is to perform any cleanup tasks or release resources that were used during the test.
    • Methods annotated with @After are commonly used to release database connections, delete temporary files, or reset the state of the system to ensure the next test starts with a clean environment.
    • If multiple methods are annotated with @After, they will be executed in the reverse order they are declared.

Here’s an example that demonstrates the usage of @Before and @After annotations:

import org.junit.Before;
import org.junit.After;
import org.junit.Test;
import static org.junit.Assert.*;

public class MyTestCase {
    private Calculator calculator;

    @Before
    public void setUp() {
        // This method will be executed before each test method
        calculator = new Calculator();
    }

    @After
    public void tearDown() {
        // This method will be executed after each test method
        calculator = null;
    }

    @Test
    public void testAddition() {
        int result = calculator.add(2, 3);
        assertEquals(5, result);
    }

    @Test
    public void testSubtraction() {
        int result = calculator.subtract(5, 3);
        assertEquals(2, result);
    }
}

In the above example, the setUp() method is annotated with @Before and is executed before each test method. It creates a new instance of the Calculator class, which will be used in the test methods.

The tearDown() method is annotated with @After and is executed after each test method. It sets the calculator object to null, releasing any resources used by it.

By using @Before and @After annotations, you can ensure that each test method starts with a clean and consistent state, and any resources used during the test are properly cleaned up after the test execution.

Understanding @BeforeClass and @AfterClass annotations

The @BeforeClass and @AfterClass annotations in JUnit are used to define methods that are executed once before and after all the test methods in a test class, respectively. These annotations allow you to perform setup and teardown operations at the class level, rather than before and after each individual test method.

  • Annotating a method with @BeforeClass indicates that it should be executed once before any of the test methods in the test class.
  • The purpose of @BeforeClass is to set up static fixtures or perform any expensive one-time initialization tasks that are common to all the test methods in the class.
  • Methods annotated with @BeforeClass should be declared as public static void and can be used, for example, to establish a database connection, load configuration files, or initialize heavy resources.
  • @BeforeClass methods are executed before any @Before or @Test methods in the class.
  • Annotating a method with @AfterClass indicates that it should be executed once after all the test methods in the test class have completed.
  • The purpose of @AfterClass is to perform cleanup or release resources that were set up in the @BeforeClass method.
  • Methods annotated with @AfterClass should be declared as public static void and can be used, for example, to close database connections, delete temporary files, or perform any necessary finalization tasks.
  • @AfterClass methods are executed after all the @After or @Test methods in the class.

Here’s an example that demonstrates the usage of @BeforeClass and @AfterClass annotations:

import org.junit.BeforeClass;
import org.junit.AfterClass;
import org.junit.Test;
import static org.junit.Assert.*;

public class MyTestCase {
    private static DatabaseConnection connection;

    @BeforeClass
    public static void setUpClass() {
        // This method will be executed once before any test method in the class
        connection = new DatabaseConnection();
        connection.connect();
    }

    @AfterClass
    public static void tearDownClass() {
        // This method will be executed once after all test methods in the class
        connection.disconnect();
        connection = null;
    }

    @Test
    public void testMethod1() {
        // Test method 1
    }

    @Test
    public void testMethod2() {
        // Test method 2
    }
}

In the above example, the setUpClass() method is annotated with @BeforeClass and is executed once before any test method in the class. It creates a DatabaseConnection instance and establishes a connection.

The tearDownClass() method is annotated with @AfterClass and is executed once after all the test methods in the class. It disconnects from the database and releases any resources.

By using @BeforeClass and @AfterClass annotations, you can perform setup and teardown operations that are shared among all the test methods in the class, saving time and resources by executing these operations only once for the entire test class.

Performance testing

In JUnit, you can use the @Test annotation with the timeout parameter to specify a maximum time limit for the execution of a test method. This is useful when you want to ensure that a test case completes within a specific timeframe, detecting potential performance issues or infinite loops.

Here’s an example of using the @Test annotation with the timeout parameter:

import org.junit.Test;

public class TimeoutTestCase {

    @Test(timeout = 1000) // Timeout set to 1 second (1000 milliseconds)
    public void testMethod() {
        // Code that should complete within the specified timeout
    }
}

In the above example, the testMethod() is annotated with @Test(timeout = 1000), which sets a timeout of 1 second for the test execution. If the test method takes longer than the specified timeout, it will be marked as a failure.

When the test is executed, if the test method takes longer than the specified timeout, a TimeoutException will be thrown, indicating that the test has failed due to exceeding the time limit.

It’s important to note that the timeout value specified is in milliseconds. You can adjust the timeout value according to your specific needs and the expected execution time of the test.

Using the timeout parameter in the @Test annotation allows you to ensure that your tests complete within a reasonable time frame, preventing them from hanging indefinitely and helping to maintain the efficiency of your test suite.

Testing for exceptions using expected attribute

In JUnit, you can use the @Test annotation with the expected parameter to specify that a test method is expected to throw a particular exception. This is useful when you want to verify that your code correctly throws an exception under certain conditions.

Here’s an example of using the @Test annotation with the expected parameter:

import org.junit.Test;

public class ExceptionTestCase {

    @Test(expected = ArithmeticException.class)
    public void testDivideByZero() {
        int result = 5 / 0; // This division will throw an ArithmeticException
    }
}

In the above example, the testDivideByZero() method is annotated with @Test(expected = ArithmeticException.class). This annotation indicates that the test expects an ArithmeticException to be thrown during the execution of the test method.

When the test is executed, if the specified exception (ArithmeticException in this case) is thrown during the execution of the test method, the test will pass. If the exception is not thrown or a different exception is thrown, the test will fail.

You can specify any exception type that you expect to be thrown by the test method using the expected parameter of the @Test annotation.

Using the expected parameter in the @Test annotation allows you to explicitly state the expected exception and verify that the code under test behaves as expected by throwing the correct exception under specific circumstances.

assertEquals() method

The assertEquals() method in JUnit is used to assert that two values are equal. It compares the expected value with the actual value, allowing you to verify that the two values are the same.

Here’s an explanation of the assertEquals() method:

import org.junit.Test;
import static org.junit.Assert.assertEquals;

public class AssertionTestCase {

    @Test
    public void testStringEquality() {
        String expected = "Hello";
        String actual = "Hello";
        assertEquals(expected, actual);
    }

    @Test
    public void testNumericEquality() {
        int expected = 42;
        int actual = 42;
        assertEquals(expected, actual);
    }
}

In the above example, the assertEquals() method is used to compare the expected and actual values. If the two values are equal, the test passes. If they are not equal, the test fails, and an assertion error is thrown.

The assertEquals() method is overloaded to handle different data types, including numeric types, strings, booleans, and objects. It performs an equality check based on the appropriate equals() method for the corresponding data type.

Additionally, you can provide an optional message as the last argument to the assertEquals() method. This message will be displayed when the assertion fails, helping to identify the reason for the failure.

The assertEquals() method is widely used in test cases to verify that a value matches the expected result. It is helpful in ensuring the correctness of calculations, method return values, and other scenarios where equality between values needs to be asserted.

assertTrue() and assertFalse() methods

The assertTrue() and assertFalse() methods in JUnit are assertion methods used to verify that a given condition is true or false, respectively. These methods are commonly used in test cases to check the expected behavior of certain conditions or boolean expressions.

Here’s an explanation of the assertTrue() and assertFalse() methods:

  • The assertTrue() method verifies that a given condition or expression is true.
  • If the condition is true, the test passes. Otherwise, if the condition is false, the test fails, and an assertion error is thrown.
  • The assertFalse() method verifies that a given condition or expression is false.
  • If the condition is false, the test passes. If the condition is true, the test fails, and an assertion error is thrown.
import org.junit.Test;
import static org.junit.Assert.assertTrue;
import static org.junit.Assert.assertFalse;

public class AssertionTestCase {

    @Test
    public void testPositiveNumber() {
        int number = 10;
        assertTrue(number > 0); // Asserts that number is greater than 0
    }

    @Test
    public void testNegativeNumber() {
        int number = -5;
        assertFalse(number > 0); // Asserts that number is not greater than 0
    }
}

In the above example, the testPositiveNumber() method uses assertTrue() to assert that the number variable is greater than 0. If the condition is true, the test passes.

The testNegativeNumber() method uses assertFalse() to assert that the number variable is not greater than 0. If the condition is false, the test passes.

If the conditions specified in assertTrue() or assertFalse() are not met during test execution, the respective assertion will fail, and an assertion error will be thrown, indicating the failure of the test.

These assertion methods provide a convenient way to validate specific conditions in your tests, making it easy to verify the expected behavior of your code based on boolean expressions or conditions.


assertArrayEquals() method

The assertArrayEquals() method in JUnit is used to assert that two arrays are equal. It compares the elements of the arrays to determine if they have the same length and contain the same elements in the same order. This assertion is useful when you want to verify the equality of array objects in your test cases.

Here’s an example of using the assertArrayEquals() method:

import org.junit.Test;
import static org.junit.Assert.assertArrayEquals;

public class ArrayTestCase {

    @Test
    public void testArrayEquality() {
        int[] expected = {1, 2, 3};
        int[] actual = {1, 2, 3};
        assertArrayEquals(expected, actual);
    }
}

In the above example, the testArrayEquality() method compares two arrays: expected and actual. The assertArrayEquals() method is used to assert that the two arrays are equal.

If the arrays have the same length and contain the same elements in the same order, the test will pass. Otherwise, if the arrays are not equal, the test will fail and an assertion error will be thrown, indicating the mismatch between the expected and actual arrays.

The assertArrayEquals() method is overloaded to support different types of arrays, including arrays of primitive types and arrays of objects. It performs deep comparison, taking into account the elements within the arrays.

It’s important to note that the order of elements in the arrays matters. If the order is significant, the elements must be in the same order in both arrays for the assertion to pass.

The assertArrayEquals() assertion is commonly used to verify the correctness of array-based calculations, data transformations, or operations that return array results. It ensures that the expected and actual arrays match exactly, helping you identify any discrepancies in the array contents.
 

ArrayList

What and Why ArrayList

ArrayList is most commonly used data structure from Collections framework.

ArrayList is an implementation of the List interface in the Java Collections Framework. It provides a resizable array-based implementation of a dynamic list, allowing you to store and manipulate elements in a flexible and efficient manner.

ArrayList allows storing duplicates and also null values. It’s important to note that ArrayList treats each occurrence of a duplicate or null value as a separate entry.

Here are some key features and reasons why you might choose to use ArrayList:

  1. Dynamic Size: ArrayList automatically adjusts its size as elements are added or removed, making it convenient for situations where the number of elements may vary over time. You do not need to worry about manually managing the underlying array’s size.
  2. Random Access: ArrayList allows for constant-time random access to elements based on their index. This means you can quickly retrieve elements from the list using the get(int index) method.
  3. Fast Iteration: ArrayList provides efficient iteration over its elements using enhanced for loops or the Iterator interface. It is particularly useful when you need to iterate through the entire list or access elements sequentially.
  4. Dynamic Modification: ArrayList supports various methods for adding, removing, and modifying elements. You can easily append elements to the end of the list (add(E element)), insert elements at specific positions (add(int index, E element)), remove elements (remove(int index) or remove(Object o)), and modify existing elements (set(int index, E element)).
  5. Backed by an Array: Internally, ArrayList is backed by an array, which provides efficient element storage and retrieval. This array-based implementation offers faster random access compared to linked data structures.
  6. Compatibility with Algorithms: ArrayList is widely used and supported in Java libraries and APIs. It is compatible with various algorithms, utility classes, and methods provided by the Java Collections Framework, making it easy to integrate with existing code.
  7. Simple and Familiar API: ArrayList has a straightforward and intuitive API, allowing for easy adoption and usage. It inherits methods from the List interface, providing a consistent interface for working with other list implementations.

However, it’s important to note that ArrayList might not be the best choice in every situation. If you frequently insert or remove elements in the middle of the list, LinkedList may offer better performance. Additionally, if thread safety is a concern, you might consider using Vector or other concurrent collection classes.

In summary, ArrayList is a commonly used implementation of the List interface, providing dynamic size, random access, fast iteration, and efficient element manipulation. It is a versatile choice for many scenarios where you need to work with ordered collections of elements.

** If appending elements to the list (or) removing the last element is a frequent operation, then you can use ArrayList as both these operations can be performed in constant time O(1) time. NOTE : While appending element, if the ArrayList internal capacity is reached, it would trigger resizing and additional time involved.


ArrayList class syntax in Java API

The syntax of the ArrayList class in the Java API is as follows:

public class ArrayList<E> extends AbstractList<E>
        implements List<E>, RandomAccess, Cloneable, Serializable {

    // Constructors
    public ArrayList();
    public ArrayList(int initialCapacity);
    public ArrayList(Collection<? extends E> c);

    // Methods
    public boolean add(E e);
    public void add(int index, E element);
    public boolean addAll(Collection<? extends E> c);
    public boolean addAll(int index, Collection<? extends E> c);
    public void clear();
    public boolean contains(Object o);
    public E get(int index);
    public int indexOf(Object o);
    public boolean isEmpty();
    public int lastIndexOf(Object o);
    public E remove(int index);
    public boolean remove(Object o);
    public boolean removeAll(Collection<?> c);
    public boolean retainAll(Collection<?> c);
    public E set(int index, E element);
    public int size();
    public List<E> subList(int fromIndex, int toIndex);
    public Object[] toArray();
    public <T> T[] toArray(T[] a);
    public void trimToSize();
}

In the above syntax, the ArrayList class is defined as a generic class (ArrayList<E>) that can work with elements of any specific type represented by the type parameter E.

The class extends the AbstractList class and implements the List interface, RandomAccess interface (indicating fast random access), Cloneable interface (supporting cloning), and Serializable interface (supporting serialization).


ArrayList – Capacity

Since an array is used internally to implement this data structure, it obviously has some size associated with it and by default it is set to 10. The capacity of an ArrayList refers to the size of this internally array.

The ArrayList class in Java dynamically resizes itself to accommodate the elements added to it. It internally maintains an array that holds the elements. The capacity of an ArrayList refers to the size of this internal array, which may be larger than the number of elements currently stored in the list.

Here are a few key points about the capacity of an ArrayList:

  1. Initial Capacity: When you create an ArrayList using the default constructor (ArrayList()), it starts with an initial capacity of 10. This means the internal array can hold up to 10 elements without needing to resize.
  2. Resizing: If you add more elements to an ArrayList and its internal array reaches its capacity, the ArrayList automatically increases the capacity by creating a new, larger array and copying the elements from the old array to the new one. This resizing process typically doubles the size of the internal array (or) in some cases, it increased by 50%.
  3. Capacity vs. Size: The capacity of an ArrayList is not the same as its size. The size refers to the number of elements currently stored in the list, while the capacity refers to the total number of elements the ArrayList can hold before it needs to resize its internal array.
  4. Controlling Capacity: If you know the expected number of elements in advance, you can specify the initial capacity when creating the ArrayList using the constructor ArrayList(int initialCapacity). This can help avoid unnecessary resizing operations if you have an estimate of the number of elements you will be adding.
  5. TrimToSize: If you want to minimize the internal array’s size to match the current number of elements, you can use the trimToSize() method. This method reduces the capacity of the ArrayList to be the same as its size, potentially saving memory if you no longer expect to add many more elements.

In summary, the capacity of an ArrayList refers to the total number of elements it can hold before needing to resize its internal array. The ArrayList class manages the capacity dynamically, automatically resizing as needed to accommodate additional elements.

** When the capacity is reached, a new array is created with a size that is 50% or double than the old array size. Old array contents are copied into the new array. However, excessive resizing due to adding large numbers of elements can impact performance, so it’s beneficial to estimate the expected size when possible.


ensureCapacity(int) method

The ensureCapacity(int) method is a method in the ArrayList class that allows you to ensure that the ArrayList has a minimum capacity specified by the parameter. It increases the capacity of the internal array, if necessary, to accommodate at least the specified number of elements without automatic resizing.

public void ensureCapacity(int minCapacity)

Here’s how the ensureCapacity(int) method works:

  1. If the current capacity of the ArrayList is less than the minCapacity parameter, the ensureCapacity(int) method increases the capacity of the internal array to be at least minCapacity. This ensures that the ArrayList can accommodate the specified number of elements without resizing.
  2. If the current capacity is already greater than or equal to the minCapacity, no resizing occurs. The ensureCapacity(int) method has no effect in this case.

Using ensureCapacity(int) can be helpful when you have an estimate of the number of elements to be added to the ArrayList. It allows you to allocate sufficient capacity in advance, reducing the number of resizing operations and improving performance.

// Ensure that the ArrayList has a minimum capacity of 20
myList.ensureCapacity(20);


trimToSize() method example

Here is the example :

import java.util.ArrayList;

public class ArrayListExample {
    public static void main(String[] args) {

        // Create an ArrayList with an initial capacity of 20
        ArrayList<String> myList = new ArrayList<>(20);

        // Add elements to the ArrayList
        myList.add("Apple");
        myList.add("Banana");
        myList.add("Orange");

        // Print the elements and size of the ArrayList before trimming
        System.out.println("Elements in the ArrayList: " + myList);
        System.out.println("Size of the ArrayList before trimming: " + myList.size());

        // Trim the ArrayList to match its size
        myList.trimToSize();

        // Print the elements and size of the ArrayList after trimming
        System.out.println("Elements in the ArrayList after trimming: " + myList);
        System.out.println("Size of the ArrayList after trimming: " + myList.size());
    }
}

In this example, we create an ArrayList called myList with an initial capacity of 20 using the ArrayList(int initialCapacity) constructor. We add elements to the myList using the add() method.

We use the trimToSize() method to trim the ArrayList to match its size, reducing the internal array’s capacity to match the number of elements.

The trimToSize() method is useful when you want to minimize the memory footprint of the ArrayList by reducing its internal array’s capacity to match the actual number of elements. This can be beneficial if you no longer expect to add many more elements to the list and want to save memory.

Note that calling trimToSize() does not affect the functionality of the ArrayList. If you subsequently add more elements, the ArrayList will automatically resize its internal array to accommodate the additional elements, as needed.


ArrayList – duplicate and null values

It’s important to note that ArrayList treats each occurrence of a duplicate or null value as a separate entry.

Duplicate Values: ArrayList permits storing duplicate values. You can add multiple occurrences of the same element to the list, and they will be stored as separate entries.

Null Values: ArrayList allows storing null values. You can add null as an element to the list without any issues.

ArrayList<String> myList = new ArrayList<>();
myList.add("Apple");
myList.add(null);
myList.add("Banana");
myList.add(null);
myList.add("Apple");

System.out.println(myList.contains(null));       // Output: true
System.out.println(myList.indexOf(null));        // Output: 1
System.out.println(myList.lastIndexOf(null));    // Output: 3

System.out.println(myList);  // Output: [Apple, null, Banana, null, Apple]


ArrayList methods

add(index, element) method

The ArrayList class in Java provides the add(int index, E element) method, which allows you to insert an element at a specific position in the list. Here’s how the add(int index, E element) method works:

public void add(int index, E element)
  • The index parameter represents the position at which you want to insert the element. It should be within the range of 0 to size() (inclusive).
  • The element parameter represents the element to be inserted at the specified index.

When you call add(int index, E element), the method inserts the specified element at the specified index in the ArrayList. The existing elements from the index onwards are shifted to the right (their indices are incremented by 1).

        // Insert an element at index 1
        myList.add(1, "Mango");

It’s important to note that the add(int index, E element) method should be used with caution, as it can potentially affect the performance for large lists. Shifting elements requires additional processing time, especially when inserting at the beginning or middle of the list.

remove(index) method

The ArrayList class in Java provides the remove(int index) method, which allows you to remove an element at a specific position in the list. Here’s how the remove(int index) method works:

public E remove(int index)
  • The index parameter represents the position of the element to be removed. It should be within the range of 0 to size() - 1 (inclusive).

When you call remove(int index), the method removes the element at the specified index from the ArrayList. The elements to the right of the removed element are shifted to the left (their indices are decremented by 1).

** The method returns the element that was removed from the list.

        // Remove the element at index 1
        String removedElement = myList.remove(1);

It’s important to note that when you remove an element using remove(int index), the indices of the subsequent elements change. Therefore, if you plan to iterate over the list using indices, be cautious when removing elements to avoid skipping or accessing the wrong elements.

boolean contains(Object o)

The contains(Object o) method is a convenient way to check for the presence of an element in an ArrayList without explicitly iterating over the list. It provides a simple and efficient way to perform membership checks.

The contains(Object o) method in the ArrayList class is used to check whether the list contains a specific element. It returns a boolean value indicating whether the specified object is present in the list or not. Here’s how the contains(Object o) method works:

public boolean contains(Object o)
  • The o parameter represents the object that you want to check for presence in the list.

When you call contains(Object o), the method checks if the specified object is present in the ArrayList. It iterates over the elements in the list and uses the equals() method to compare the specified object with each element. If a matching element is found, the method returns true. If the specified object is not found in the list or if the list is empty, the method returns false.

        // Create an ArrayList
        ArrayList<String> myList = new ArrayList<>();

        // Add elements to the ArrayList
        myList.add("Apple");
        myList.add("Banana");
        myList.add("Orange");

        // Check if "Banana" is present in the ArrayList
        boolean containsBanana = myList.contains("Banana");
        System.out.println("ArrayList contains 'Banana': " + containsBanana);
 // true

We then use the contains("Banana") method to check if the ArrayList contains the element “Banana”. The method returns true because “Banana” is present in the list.

contains(Object o) relation with equals() method

The contains(Object o) method in the ArrayList class uses the equals() method to determine whether the specified object is present in the list.

When contains(Object o) is called, it iterates over the elements in the ArrayList and calls the equals() method on each element to compare it with the specified object o. By using equals(), the method can perform customized equality checks if the element class overrides the equals() method.

By default, the equals() method in the Object class compares the references of objects, which means two different instances with the same content are considered unequal. However, many classes in Java, including String, Integer, and custom classes, override the equals() method to provide meaningful equality comparisons based on their internal state.

Therefore, when using contains(Object o) with an ArrayList, it’s important to consider how the equals() method is defined for the objects you are working with.

** If you’re working with custom classes, you may need to override the equals() method to ensure proper equality comparisons according to your specific requirements.

By relying on the equals() method, contains(Object o) provides flexibility to handle various types of objects and supports customized equality comparisons, making it suitable for general use cases.

NOTE – The methods contains(), indexOf(), lastIndexOf() – all these methods use equals() method to compare the object with each of the element in the list.


boolean removeAll(Collection<?> c) method

The removeAll(Collection<?> c) method in the ArrayList class is used to remove all elements from the list that are contained in the specified collection.

Here’s how the removeAll(Collection<?> c) method works internally:

  1. Iteration: The removeAll(Collection<?> c) method iterates over each element in the specified collection (c).
  2. Element Comparison: For each element in the specified collection, the removeAll method internally calls the remove(Object o) method to remove all occurrences of that element from the ArrayList. It uses the equals() method to determine the equality between the elements.
  3. Removal: When remove(Object o) is called, it iterates over the elements in the ArrayList and removes all occurrences of the specified object o. This is achieved by shifting the subsequent elements to the left and updating the size of the ArrayList accordingly.
  4. Iteration Completion: After iterating through all the elements in the specified collection, the removeAll method completes the removal process.

The removeAll(Collection<?> c) method returns true if at least one element was removed from the ArrayList. If no elements were removed, it returns false.

Here’s an example that demonstrates the usage of the removeAll(Collection<?> c) method:

import java.util.ArrayList;
import java.util.Arrays;
import java.util.List;

public class ArrayListExample {
    public static void main(String[] args) {
        // Create an ArrayList
        ArrayList<String> myList = new ArrayList<>(Arrays.asList("Apple", "Banana", "Orange", "Apple"));

        System.out.println("ArrayList before removeAll: " + myList);

        // Create a collection with elements to remove
        List<String> toRemove = Arrays.asList("Apple", "Orange");

        // Remove elements from the ArrayList
        boolean removed = myList.removeAll(toRemove);

        System.out.println("Elements removed: " + removed);
        System.out.println("ArrayList after removeAll: " + myList);
    }
}

Output :

ArrayList before removeAll: [Apple, Banana, Orange, Apple]
Elements removed: true
ArrayList after removeAll: [Banana]

We use the removeAll(toRemove) method to remove all occurrences of the elements in the toRemove collection from the ArrayList. In this case, “Apple” and “Orange” are removed.

Internally, the removeAll(Collection<?> c) method iterates over the elements in the specified collection, calls contains() method and if element is present, removes the matching element from the ArrayList, using the remove(Object o) method. It repeats this process for each element in the collection until all occurrences are removed.


ArrayList example

Here’s an example that demonstrates the usage of various methods in the ArrayList class :

import java.util.ArrayList;

public class ArrayListExample {
    public static void main(String[] args) {
        // Create an ArrayList
        ArrayList<String> myList = new ArrayList<>();

        // Add elements to the ArrayList
        myList.add("Apple");
        myList.add("Banana");
        myList.add("Orange");

        // Accessing elements using get() method
        System.out.println("Element at index 0: " + myList.get(0));
        System.out.println("Element at index 1: " + myList.get(1));
        System.out.println("Element at index 2: " + myList.get(2));

        // Modifying elements using set() method
        myList.set(1, "Grapes");

        // Printing the modified ArrayList
        System.out.println("Modified ArrayList: " + myList);

        // Checking the size of the ArrayList
        System.out.println("Size of ArrayList: " + myList.size());

        // Checking if the ArrayList is empty
        System.out.println("Is ArrayList empty? " + myList.isEmpty());
    }
}

Output :

Element at index 0: Apple
Element at index 1: Banana
Element at index 2: Orange
Modified ArrayList: [Apple, Grapes, Orange]
Size of ArrayList: 3
Is ArrayList empty? false

In the above example:

  1. We create an ArrayList called myList.
  2. We use the add() method to add three elements (“Apple”, “Banana”, and “Orange”) to the ArrayList.
  3. We use the get() method to access and print the elements at specific indices (0, 1, and 2).
  4. We use the set() method to modify the element at index 1, replacing “Banana” with “Grapes”.
  5. We print the modified ArrayList using System.out.println().
  6. We use the size() method to check the size of the ArrayList and print it.
  7. We use the isEmpty() method to check if the ArrayList is empty (contains no elements) and print the result.

Another example :

import java.util.ArrayList;

public class ArrayListExample {
    public static void main(String[] args) {
        // Create an ArrayList
        ArrayList<String> myList = new ArrayList<>();

        // Add elements to the ArrayList
        myList.add("Apple");
        myList.add("Banana");
        myList.add("Orange");

        // Accessing elements using get() method
        System.out.println("Element at index 0: " + myList.get(0));
        System.out.println("Element at index 1: " + myList.get(1));
        System.out.println("Element at index 2: " + myList.get(2));

        // Modifying elements using set() method
        myList.set(1, "Grapes");

        // Printing the modified ArrayList
        System.out.println("Modified ArrayList: " + myList);

        // Checking the size of the ArrayList
        System.out.println("Size of ArrayList: " + myList.size());

        // Checking if the ArrayList is empty
        System.out.println("Is ArrayList empty? " + myList.isEmpty());

        // Removing elements using remove() method
        myList.remove("Apple");

        // Printing the ArrayList after removing an element
        System.out.println("ArrayList after removing an element: " + myList);

        // Removing all elements using removeAll() method
        myList.removeAll(myList);

        // Printing the ArrayList after removing all elements
        System.out.println("ArrayList after removing all elements: " + myList);

        // Adding elements to the ArrayList again
        myList.add("Mango");
        myList.add("Pineapple");

        // Iterating over elements using an enhanced for loop
        System.out.println("Iterating over elements:");
        for (String element : myList) {
            System.out.println(element);
        }
    }
}

Output :

Element at index 0: Apple
Element at index 1: Banana
Element at index 2: Orange
Modified ArrayList: [Apple, Grapes, Orange]
Size of ArrayList: 3
Is ArrayList empty? false
ArrayList after removing an element: [Grapes, Orange]
ArrayList after removing all elements: []
Iterating over elements:
Mango
Pineapple

In the above example:

  1. We create an ArrayList called myList.
  2. We use the add() method to add three elements (“Apple”, “Banana”, and “Orange”) to the ArrayList.
  3. We use the get() method to access and print the elements at specific indices (0, 1, and 2).
  4. We use the set() method to modify the element at index 1, replacing “Banana” with “Grapes”.
  5. We print the modified ArrayList using System.out.println().
  6. We use the size() method to check the size of the ArrayList and print it.
  7. We use the isEmpty() method to check if the ArrayList is empty (contains no elements) and print the result.
  8. We use the remove() method to remove the element “Apple” from the ArrayList.
  9. We print the ArrayList after removing an element.
  10. We use the removeAll() method to remove all elements from the ArrayList.
  11. We print the ArrayList after removing all elements.
  12. We add elements “Mango” and “Pineapple” to the ArrayList again.
  13. We use an enhanced for loop to iterate over the elements in the ArrayList and print each element.

List Interface

What and Why List interface

The List interface in Java is used when you need to store a collection of elements in a specific order that allows duplicate elements. It is part of the Java Collections Framework and provides a flexible and powerful way to manage and manipulate ordered collections.

Here are some reasons why you would use the List interface in Java:

  1. Order Preservation: The List interface maintains the order of elements as they are inserted. This allows you to access elements by their index and perform operations like appending, inserting, and removing elements at specific positions.
  2. Indexed Access: List provides direct access to elements based on their index using methods like get(int index). This makes it convenient to retrieve and modify elements at specific positions within the list.
  3. Duplicate Elements: Unlike other collection types like Set, List allows duplicate elements. You can add multiple occurrences of the same element to the list, and they will be stored as separate entries.
  4. Dynamic Size: List implementations, such as ArrayList or LinkedList, automatically handle resizing as elements are added or removed. This allows you to dynamically change the size of the list without needing to manage the underlying data structure manually.
  5. Iteration and Manipulation: The List interface provides several methods to iterate over elements, such as enhanced for loop, Iterator, or ListIterator. It also offers numerous methods to add, remove, or modify elements, allowing you to perform various operations on the collection.
  6. Compatibility with Algorithms: The List interface is widely used in Java libraries and APIs. It is compatible with numerous algorithms, sorting methods, and utility classes provided by the Java Collections Framework. It allows you to leverage the rich functionality available for working with ordered collections.
  7. Flexibility: The List interface has various implementations to choose from, depending on your specific requirements. For example, ArrayList provides fast element access and manipulation, while LinkedList offers efficient insertion and removal at both ends of the list.

Overall, the List interface is suitable when you need to manage ordered collections that allow duplicates and require frequent access to elements based on their position. It provides a rich set of methods and compatibility with existing Java libraries, making it a versatile choice for many use cases.


List interface syntax as in Java API

The syntax of the List interface in the Java API is as follows :

public interface List<E> extends Collection<E> {
    // Positional Access
    E get(int index);
    E set(int index, E element); // inserts and returns previous element at index.
    void add(int index, E element);
    void add(E element); // adds to the end of list
    E remove(int index);
    boolean addAll(int index, Collection<? extends E> c); // add all from Collection

    // Search Operations
    int indexOf(Object o); // returns -1 if object not found
    int lastIndexOf(Object o);

    // List Iterators
    ListIterator<E> listIterator();
    ListIterator<E> listIterator(int index);

    // View Operations
    List<E> subList(int fromIndex, int toIndex);
}

In the above syntax, the List interface is defined as a generic interface (List<E>) that can work with elements of any specific type represented by the type parameter E.

The interface extends the Collection interface, inheriting its methods and adding additional methods specific to lists.

The List interface includes methods categorized into positional access, search operations, list iterators, and view operations.

The positional access methods include get(int index), set(int index, E element), add(int index, E element), and remove(int index). These methods allow you to retrieve an element at a specific index, modify the element at a given index, insert an element at a particular index, and remove an element at a specific index, respectively.

The search operations methods are indexOf(Object o) and lastIndexOf(Object o). These methods return the index of the first occurrence and the last occurrence of the specified object in the list, respectively. If the object is not found, these methods return -1.

The list iterator methods are listIterator() and listIterator(int index). These methods return a ListIterator that allows bidirectional iteration over the elements of the list. The second variant allows you to specify the starting position for the iterator.

  • ListIterator is a sub interface of Iterator interface.

The range view operation method is subList(int fromIndex, int toIndex). This method returns a view of the list between the specified fromIndex (inclusive) and toIndex (exclusive).

  • Returned list is backed by the original list, meaning any change made in the returned list will be reflected in original list and vice versa. Changes to the sublist will be reflected in the original list and vice versa.
  • ** To the returned list, we can do both data related changes(meaning updating data) or structural changes like adding / removing elements etc. The changes will get reflected in original list. However, to the original list, if we do any structural changes like adding / removing elements, then the returned list which is the view, will be invalidated and trying to access elements using returned list will throw ConcurrentModificationException.

Note that the List interface inherits other methods from the Collection interface, such as add(E e), remove(Object o), contains(Object o), size(), isEmpty(), addAll(Collection<? extends E> c), removeAll(Collection<?> c), retainAll(Collection<?> c), containsAll(Collection<?> c), toArray(), and toArray(T[] a).

The List interface serves as a contract for list implementations and provides a wide range of methods to manage ordered collections.